Category: Uncategorized

  • Five reasons “AI BI” without governance fails in regulated industries

    Five reasons “AI BI” without governance fails in regulated industries

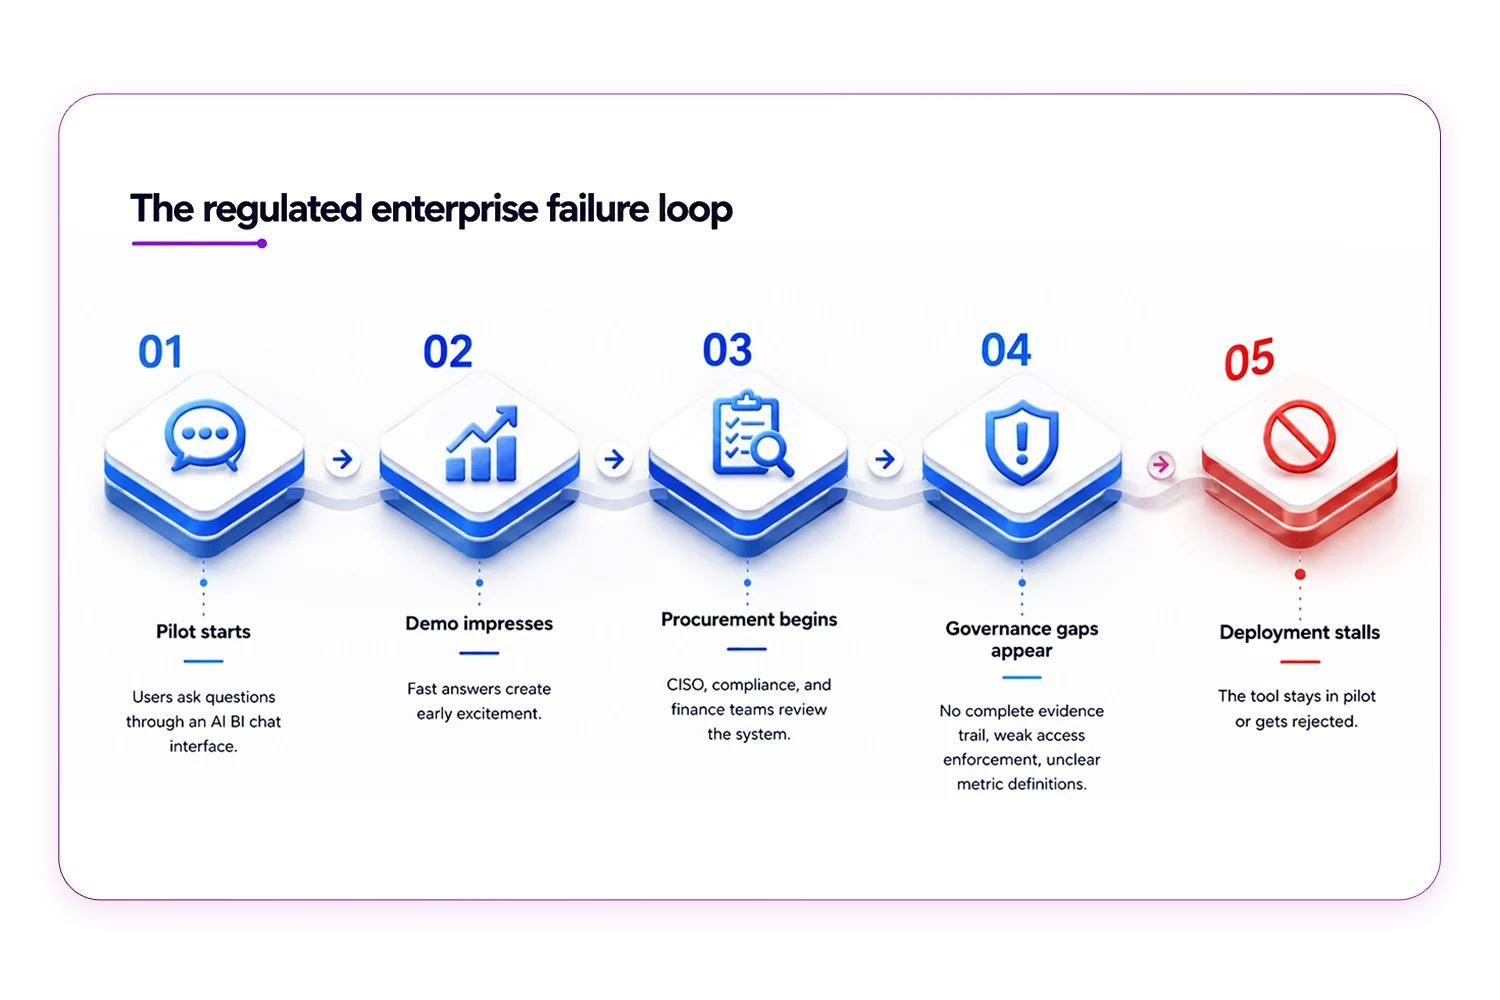
    Regulated enterprises do not get to fail quietly. When a bank, an insurer, or a health system deploys analytics software that produces an indefensible number, the consequence is not an internal retrospective. It is an audit finding, a regulatory inquiry, or a remediation programme with a budget line. This is why the wave of “AI BI” tools, chat interfaces bolted onto warehouses with a capable model underneath, keeps stalling at exactly the same stage in regulated industries: the pilot impresses, the procurement review begins, and the deployment dies. The failure is not the model. It is the absence of governance, and it fails in five specific ways.

    Reason one: answers that cannot be evidenced are answers that cannot be used

    Regulated industries run on evidence. A number that reaches a regulator, an external auditor, or a filing must be supportable with documentation of its origin. An ungoverned AI BI tool produces answers in a chat window and retains, at best, a conversation history. There is no linked record of who asked, what SQL ran, which tables were read, or which definitions were applied. The tool’s answers may be perfectly correct, but correctness without evidence has no standing in a regulated process. The output is unusable for exactly the decisions that matter most, which confines the tool to trivia and guarantees it never justifies its cost.

    Reason two: uncontrolled definitions produce contradictory numbers in official places

    A model reading a raw schema must guess what the business means by its own vocabulary. Which of several revenue columns is the certified one? Are written premiums gross or net of reinsurance here? Does this health system count readmissions within 30 days or 90? An ungoverned tool answers these questions differently depending on phrasing, context, and chance. In an unregulated setting, that produces confusion. In a regulated one, it produces two different figures for the same metric in two official documents, and reconciling contradictory reported numbers is a process no compliance team enjoys. Without a certified semantic layer, this outcome is not a risk. It is a schedule.

    Reason three: access control that lives outside the query path is access control in name only

    Regulated data carries entitlement rules with legal force: patient records under health privacy law, material non-public information inside financial institutions, policyholder data under insurance regulation. Many AI BI tools connect to the warehouse through a single service account with broad read access, then rely on the application layer to decide what users should see. The moment the model generates an unanticipated query, that arrangement leaks. Governance means the agent inherits the asker’s permissions and enforces them at query time, so the question a user is not entitled to ask returns nothing, structurally, rather than being filtered by hope. Regulators examine the structural version. They penalise the other one.
    Reason four: hallucinated analysis is fluent, and fluency defeats casual review

    The dangerous failure mode of an ungoverned tool is not the visibly wrong answer. It is the plausible one: a well-formed figure, confidently presented, resting on a silently invented join or a misread column. Human review catches this only when the reviewer independently reproduces the work, which eliminates the time savings that justified the tool. Governed platforms attack this differently: grounding generation in certified definitions so there is less room to invent, and attaching the generated SQL and sources to every answer so verification takes minutes instead of hours. In a regulated industry, where an incorrect figure can constitute a reporting breach rather than an embarrassment, this difference is the whole game.

    Reason five: the veto holders were never going to approve it

    Enterprise AI deployments in regulated industries pass through three offices that each hold a veto: the CISO, the head of compliance, and increasingly the CFO. Each asks a governance question. The CISO asks how access is enforced and where data travels, including whether it leaves for a model vendor the organisation has not approved. Compliance asks how the system’s decisions will be documented for examiners. The CFO asks how a number can be traced when challenged. An ungoverned tool has no answer for any of the three, which means the deployment fails in procurement no matter how well the pilot went. The pattern repeats so reliably that it should be treated as a law of the category: in regulated industries, governance is not a feature of the deployment. It is the precondition for there being a deployment at all.
    The conclusion regulated buyers are reaching

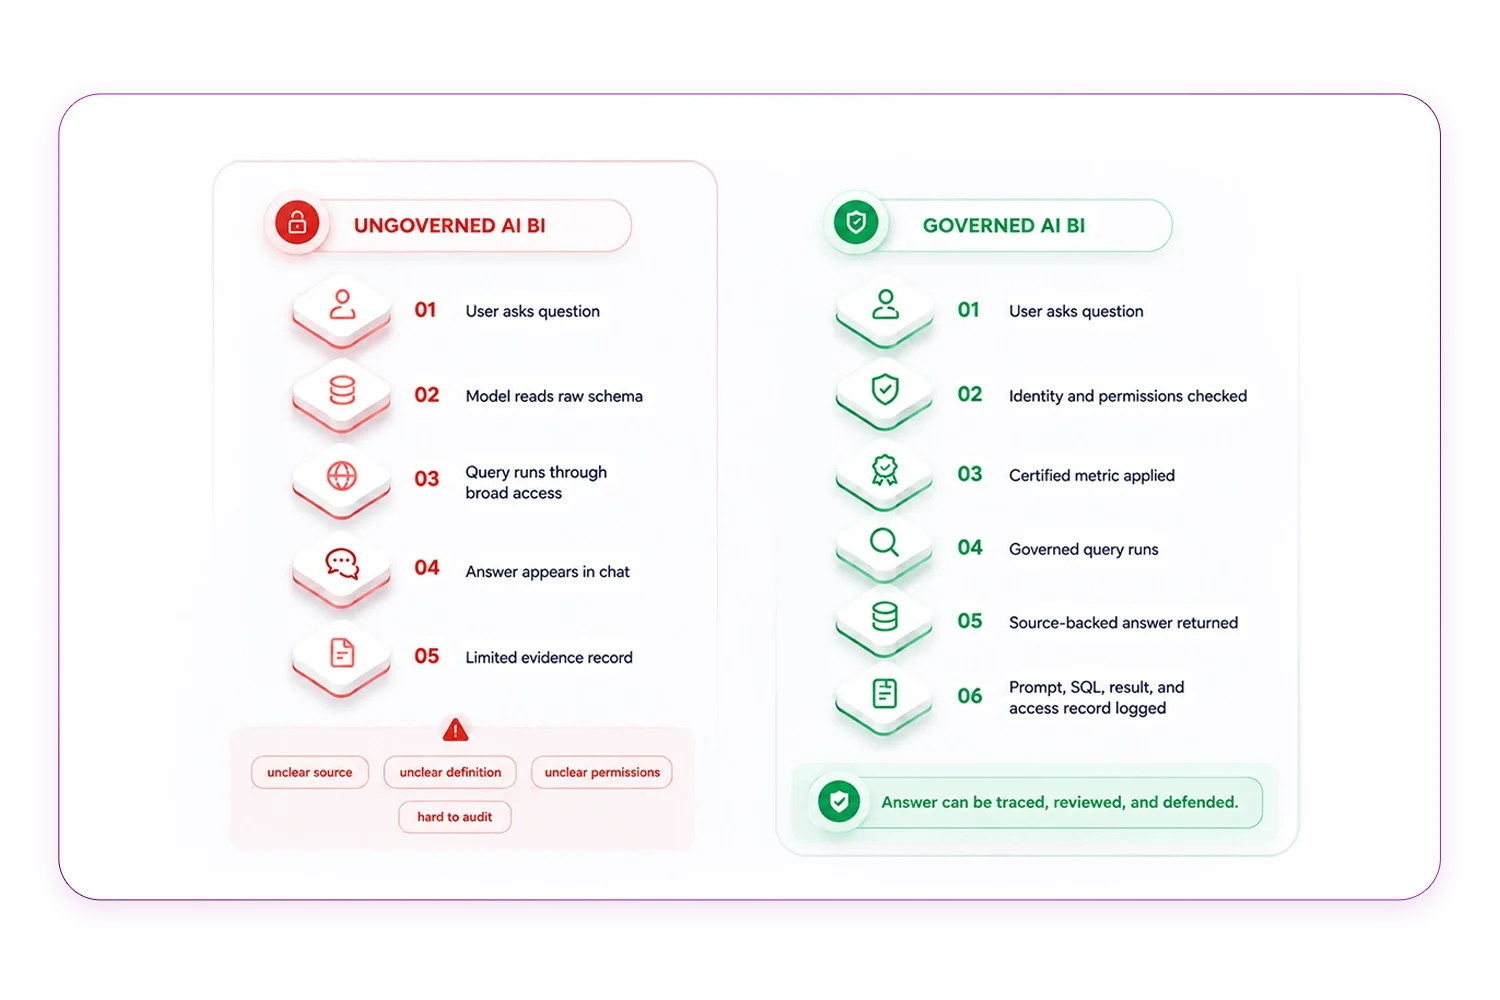
    None of these five failures is cured by a better model, because none of them is a capability problem. They are control problems, and controls have to be architectural: a certified semantic layer, permissions enforced at query time, a complete prompt-level audit trail, and model choice the enterprise can direct. Platforms built this way clear the vetoes that kill their ungoverned rivals, and the results follow deployment rather than remaining in pilots. Based on QuaerisAI customer deployments and published materials, governed deployments have achieved BI adoption rates of 30 to 60 percent and reductions in BI cost of 70 percent, outcomes that are only available to tools that regulated enterprises are actually permitted to use.

    Frequently asked questions

    What counts as “AI BI without governance”?

    Any deployment where a language model generates analysis against enterprise data without three controls in place: certified metric definitions the model must use, user-level access permissions enforced when the query executes, and a complete linked record of each interaction from prompt to SQL to result. A tool can be highly capable and still be ungoverned. The two properties are independent.

    Are regulated industries simply late adopters of AI analytics?

    No. They are early adopters of governed AI analytics and non-adopters of ungoverned AI analytics. The demand for faster answers is at least as strong in banking, insurance, and healthcare as anywhere else. What differs is that these industries cannot absorb the failure modes of ungoverned tools, so they wait for platforms where the controls are structural.

    Can governance be added to an existing AI BI deployment later?

    Partially, and expensively. Access enforcement and audit trails must live inside the query pipeline to be complete, which usually means the platform has to be built for them. Retrofitting typically produces fragmented logs and application-layer filtering, which are exactly the versions that fail examination. The practical answer is to evaluate for governance at selection, not remediation.
  • The shadow AI tax: what ungoverned AI use is quietly costing your data team

    The shadow AI tax: what ungoverned AI use is quietly costing your data team

    A data analyst at a mid-size logistics company spent forty minutes on a Tuesday afternoon reconstructing a churn number from scratch. Not because the number didn’t exist anywhere. Because someone in sales had already pulled a number from a public chatbot, brought it into a leadership meeting that morning, and now the analyst had to prove it right or wrong before anyone would trust either version.

    The number turned out to be close, but built on a customer segment definition that didn’t match what finance used. Nobody in that meeting knew that. They just knew there were now two churn numbers in the building, and someone had to lose the argument about which one was real.

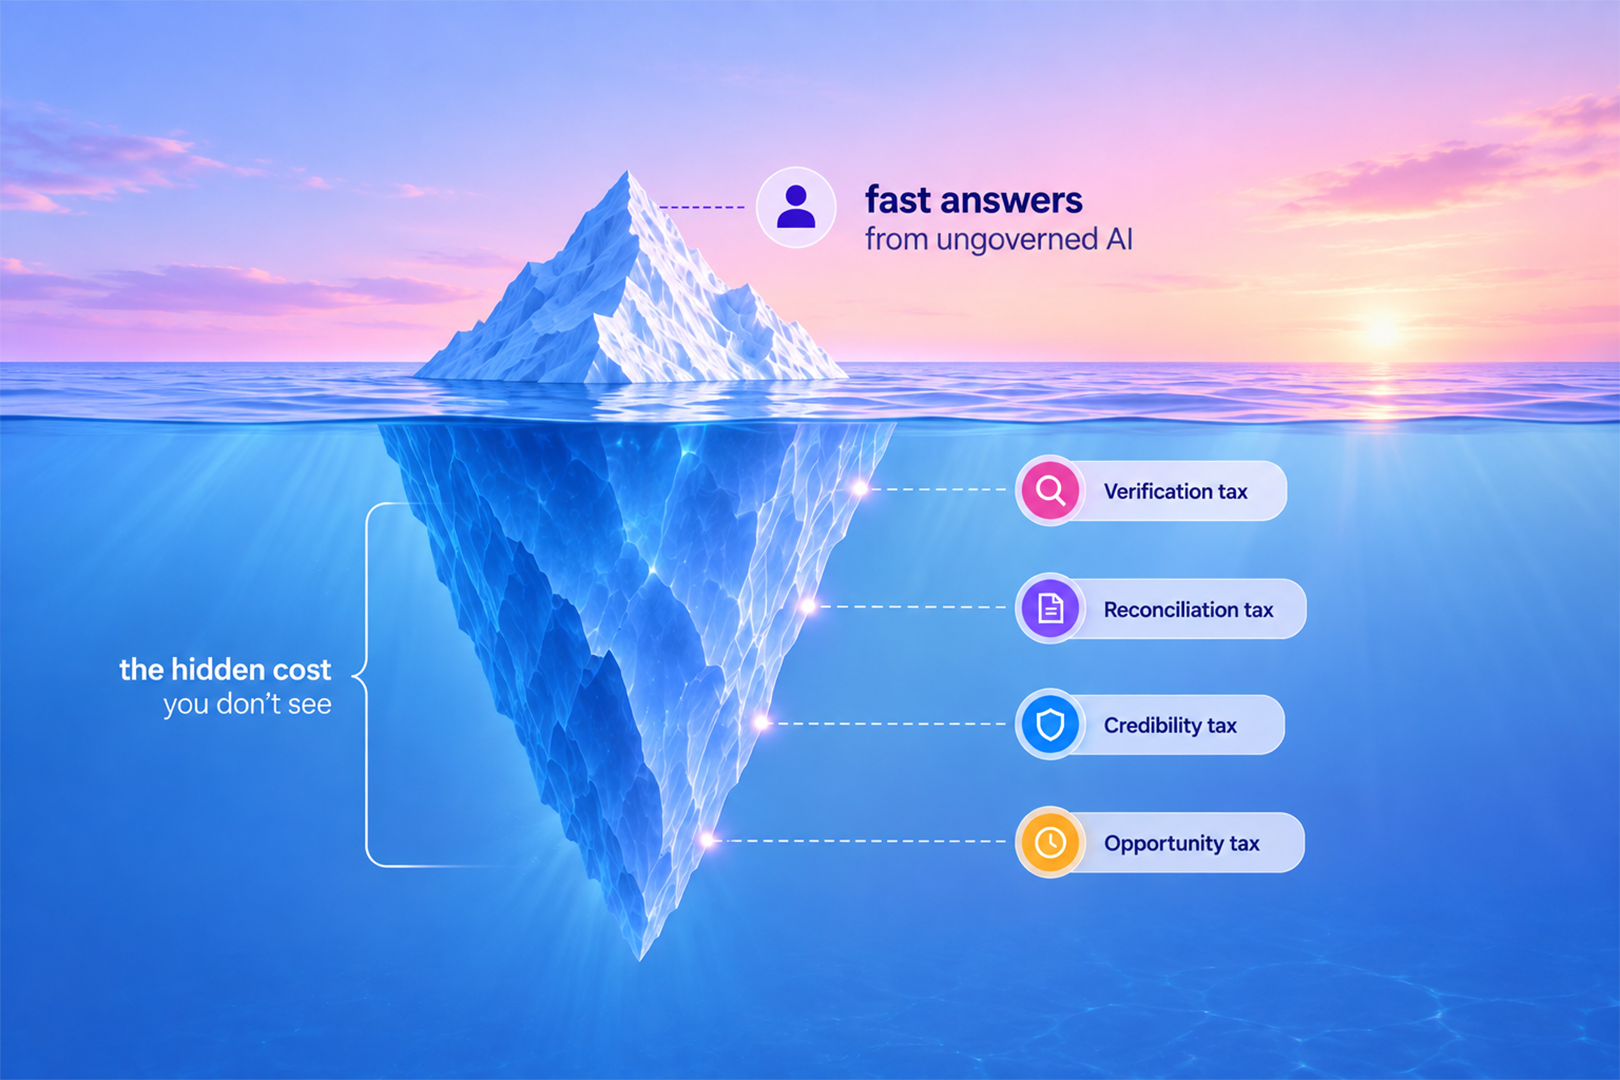
    This is the actual cost of shadow AI, and it rarely shows up in the way risk conversations describe it.

    The tax isn’t where most people are looking

    Most discussion of ungoverned AI use frames it as a security problem: sensitive data pasted into a public chatbot, sitting somewhere outside the company’s control. That risk is real. It is also not where the recurring cost lives.

    The recurring cost lives downstream, on the data team, every time an ungoverned answer reenters the business as if it were a governed one. Someone asked a chatbot a question, got a plausible number, and used it. The data team didn’t produce that number and usually doesn’t find out it exists until it conflicts with something they did produce. At that point, the work isn’t optional. Someone has to figure out where the number came from, what it means, and why it doesn’t match, before the disagreement can even be resolved, let alone closed.

    That work is a tax. It gets paid every time it happens, and almost nobody is tracking the total.

    What the tax actually looks like

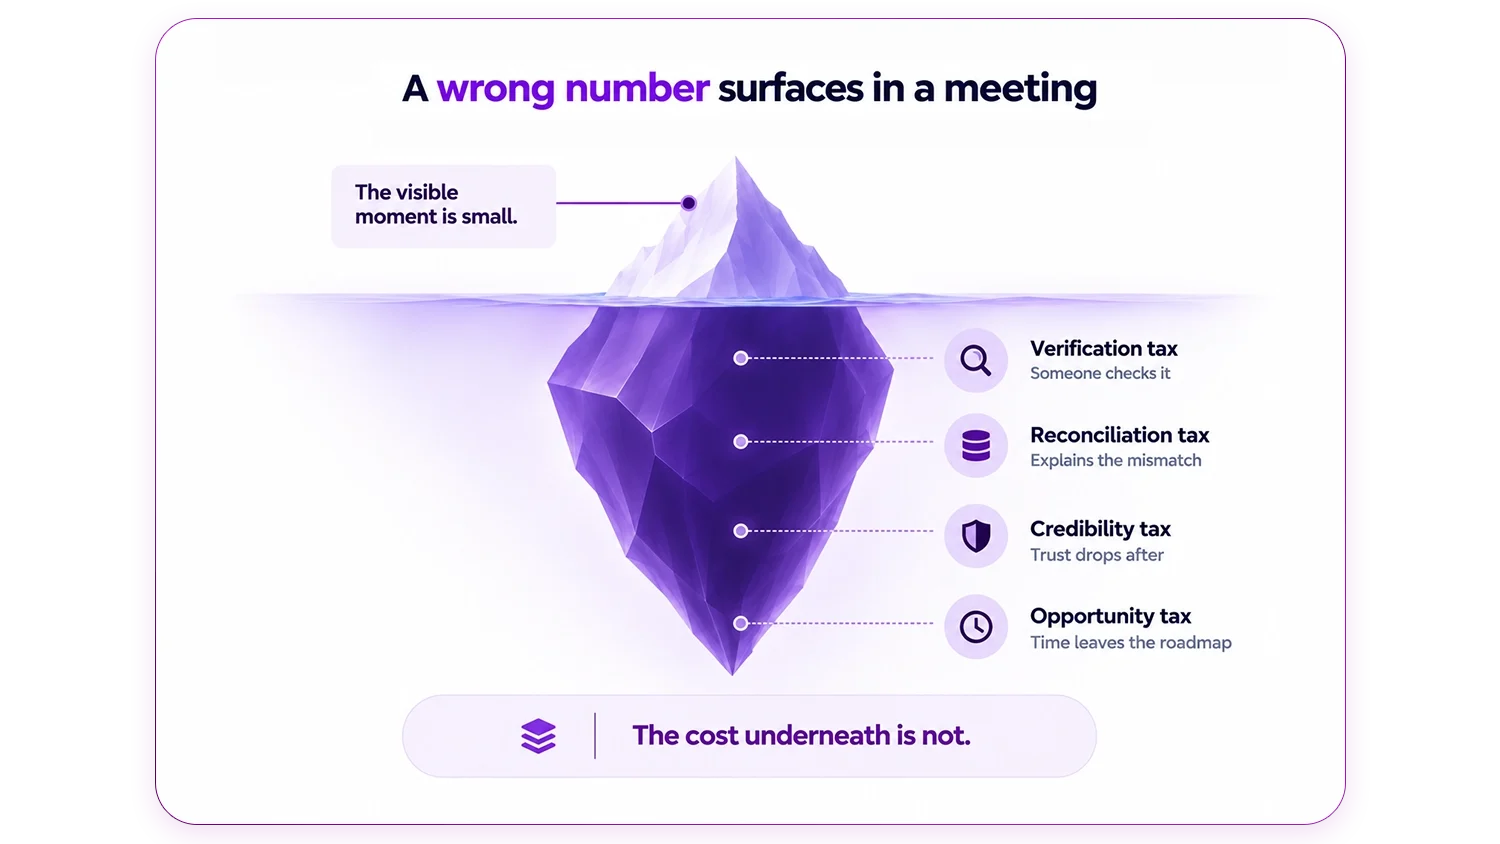
    The verification tax. Every ungoverned number that reaches a meeting eventually needs someone to check it. That checking work rarely gets scheduled. It gets absorbed, usually by whoever is already stretched thin, at the exact moment a decision is waiting on the answer.

    The reconciliation tax. Two numbers in a room means someone has to explain the gap. That explanation almost never has a quick answer, because the gap is usually a definitional mismatch: a different date range, a different customer segment, a different join that nobody wrote down. Resolving it means reverse engineering a query nobody kept a record of.

    The credibility tax. Once a wrong number has been in a meeting, the data team’s numbers get a second look too, even the correct ones. Trust doesn’t erode evenly. One bad number from an ungoverned source can quietly increase scrutiny on everything the data team produces afterward, whether that scrutiny is warranted or not.

    The opportunity tax. All of that verification and reconciliation time comes from somewhere. It comes from the roadmap, the actual analysis work the data team was supposed to be doing instead of playing defense against an answer they didn’t produce.

    None of these show up on a dashboard. They show up as a data team that seems perpetually behind, without anyone being able to point to exactly why.

    Banning the tool doesn’t remove the tax

    The instinctive response to this is to block public AI tools at the network level and call the problem solved. It rarely works, and when it does work, it usually just moves the cost somewhere less visible. The underlying need, a fast answer to a specific business question, does not go away because the tool got blocked. It moves to a personal device, a different account, a colleague who still has access. The tax stays the same. The visibility into it gets worse.

    Blocking access without offering a governed alternative treats the symptom and leaves the actual cause in place: business users have a real question and no fast, trustworthy way to ask it.

    What actually removes the tax

    The only way to remove the verification and reconciliation tax is to remove the reason it exists: a governed answer has to be at least as fast as an ungoverned one, or the ungoverned path stays attractive no matter what the policy says.

    That means conversational access to data that resolves through certified definitions instead of a model’s best guess. When gross margin means the same thing everywhere it’s asked, and the answer comes with a citation back to the source table and the definition version behind it, there is nothing left to reconcile. The number that shows up in the meeting is the number the data team would have produced anyway, because it came from the same governed pipeline.

    It also means every question leaves a prompt-level record: who asked, what was resolved, what ran, what came back. When a number is challenged, the answer to “where did this come from” is a lookup, not an investigation.

    This is not a security control bolted onto an existing BI stack. It is what removes the actual incentive for the shadow path to exist in the first place, because the sanctioned path stops being slower.

    The real question to ask

    The shadow AI tax rarely gets calculated directly, because it is spread across dozens of small interruptions rather than one visible incident. A more useful exercise than trying to measure it after the fact is asking the data team a simpler question: how many hours this month went toward verifying, reconciling, or explaining a number that didn’t originate with them?

    Whatever that number turns out to be, it is not a cost the business decided to pay. It is a cost that accumulated because the sanctioned path was slower than the alternative. Fixing that gap is what actually stops the tax from being collected again next month.

  • How to tell if your organization already has a shadow AI problem

    How to tell if your organization already has a shadow AI problem

    A wrong number rarely gets caught the first time it’s said out loud in a meeting. It gets caught the third time, once it has already shaped a decision or two, when someone finally asks where it came from.

    That delay is the actual challenge with shadow AI. It doesn’t announce itself. There’s no login screen, no request ticket, no line item anywhere that says “business question answered outside governed systems.” The evidence is scattered across normal-looking behavior that only reads as a pattern once someone is looking for it.

    Here’s what to actually look for, and what it usually means when you find it.

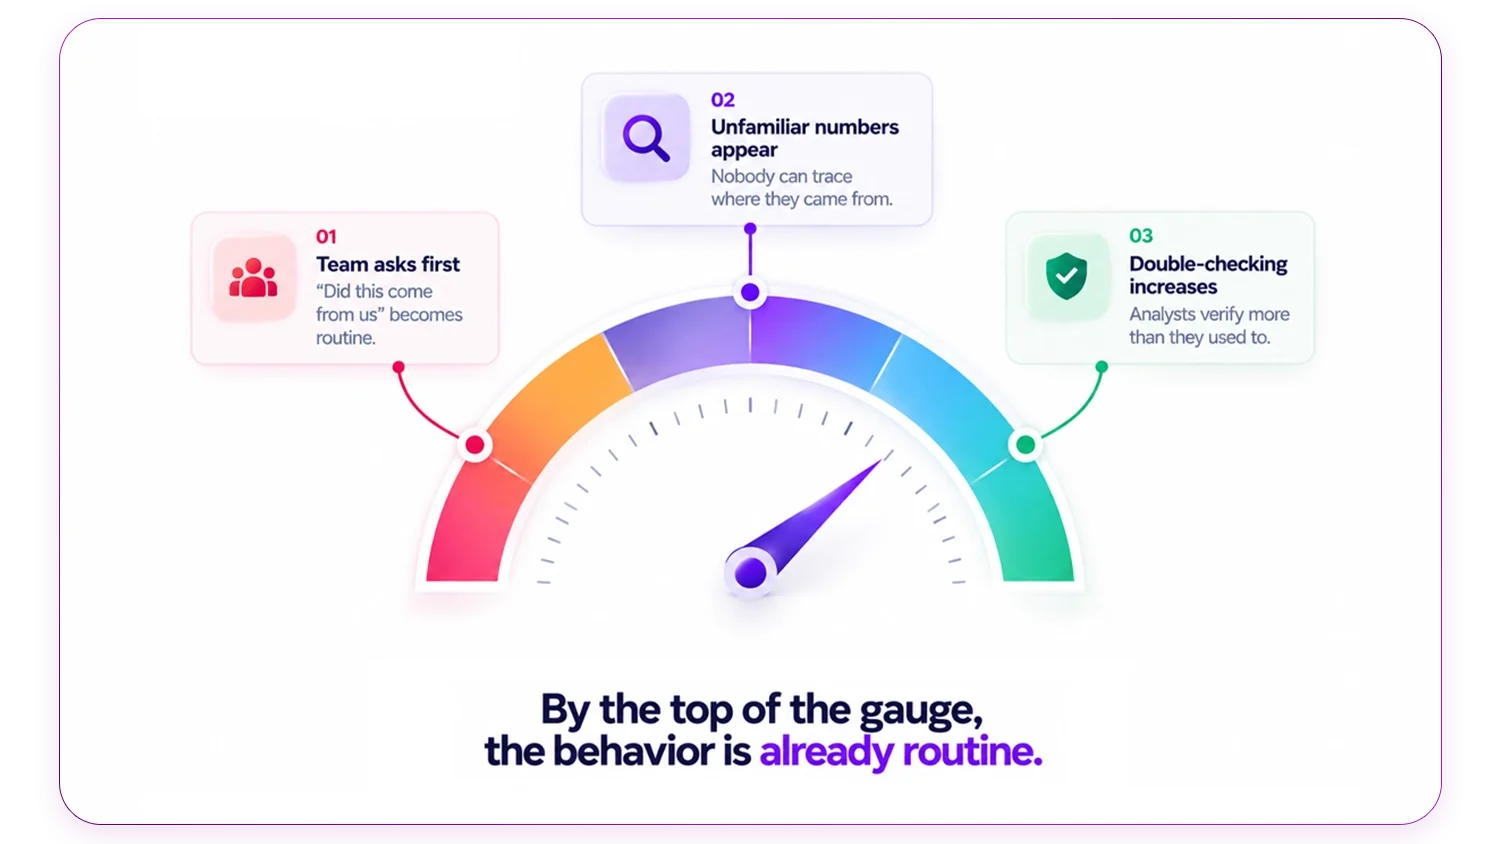
    Analysts talk about double-checking more than they used to

    Listen for a specific phrase: “let me just double-check that.” If it’s coming up more often, especially attached to numbers the analyst didn’t personally produce, that’s usually a sign someone upstream got an answer from somewhere other than the governed system and brought it into a conversation as if it were settled.

    The double-checking itself isn’t the problem. It’s a reasonable response to uncertainty. The problem is what created the uncertainty in the first place: a number entered circulation without going through anything the data team controls.

    A number shows up that nobody on the data team recognizes

    This is usually the first hard signal, and it typically arrives sideways. Someone references a figure in a meeting, a data team member hears it, and has a moment of “wait, where did that come from?” If that moment is happening even occasionally, it’s worth treating as a signal rather than a one-off.

    The specific tell is not that the number is wrong. Sometimes it’s approximately right. The tell is that nobody can trace it back to a query, a report, or a person who built it deliberately.

    People describe getting answers “faster” from somewhere else

    If you hear language like “I just asked it directly” or “it was quicker to check myself,” pay attention to what “it” refers to. Often this is completely legitimate, someone found a faster path through an approved tool. Sometimes it isn’t, and the faster path is a public AI assistant that has no connection to certified definitions, no access controls, and no record of what was asked or answered.

    The distinguishing question is simple: can the data team see what was asked and what came back? If the honest answer is no, the speed came from somewhere ungoverned.

    Reconciliation requests are increasing

    A rising number of “why doesn’t this match” questions is one of the more measurable signals available, because it usually leaves a trail in tickets, Slack threads, or email. If reconciliation requests are trending up without a clear cause like a new data source or a metric redefinition, ungoverned answers entering circulation is a reasonable hypothesis to test.

    The pattern to watch for specifically is reconciliation requests where the second number has no clear origin. A mismatch between two known systems is a data quality issue. A mismatch where one side traces to nothing is usually shadow AI.

    Nobody can say with confidence where a specific number came from

    This is the clearest version of the problem, and also the hardest one to notice, because the absence of an answer doesn’t feel like an event. Try it as a direct exercise: pick a number that appeared in a recent leadership deck and ask whoever presented it to trace its exact origin, the source table, the definition used, the person or system that produced it.

    If that trace takes more than a few minutes, or comes back with genuine uncertainty, that’s not a one-time gap. It’s evidence of how numbers are currently entering the organization, and it will keep happening the same way until something changes about the path itself.

    The data team has started asking “did this come from us?” first

    This is a late-stage signal, and it means the organization has already been through enough incidents that the data team has adapted its default posture. When “did this come from us” becomes a routine first question rather than an unusual one, the shadow AI problem has been present long enough to change behavior, not just create occasional friction.

    What to do with this list

    None of these signals alone proves anything. A single moment of double-checking, a single unfamiliar number, a single fast answer, all of those happen in healthy organizations too. What matters is whether several of these are showing up together and trending in the same direction.

    If they are, the next step is not a policy memo banning specific tools. That tends to move the behavior somewhere less visible rather than removing it, since the underlying need for a fast answer to a business question doesn’t disappear because the tool got blocked.

    The more durable fix is making the governed path at least as fast as the ungoverned one: conversational access to data that resolves through certified definitions, with every question and answer logged automatically. When the sanctioned path is no slower than the alternative, there’s no longer a reason for the alternative to exist quietly in the background.

  • The shadow-AI problem: when analysts ask ChatGPT instead of your BI tool

    The shadow-AI problem: when analysts ask ChatGPT instead of your BI tool

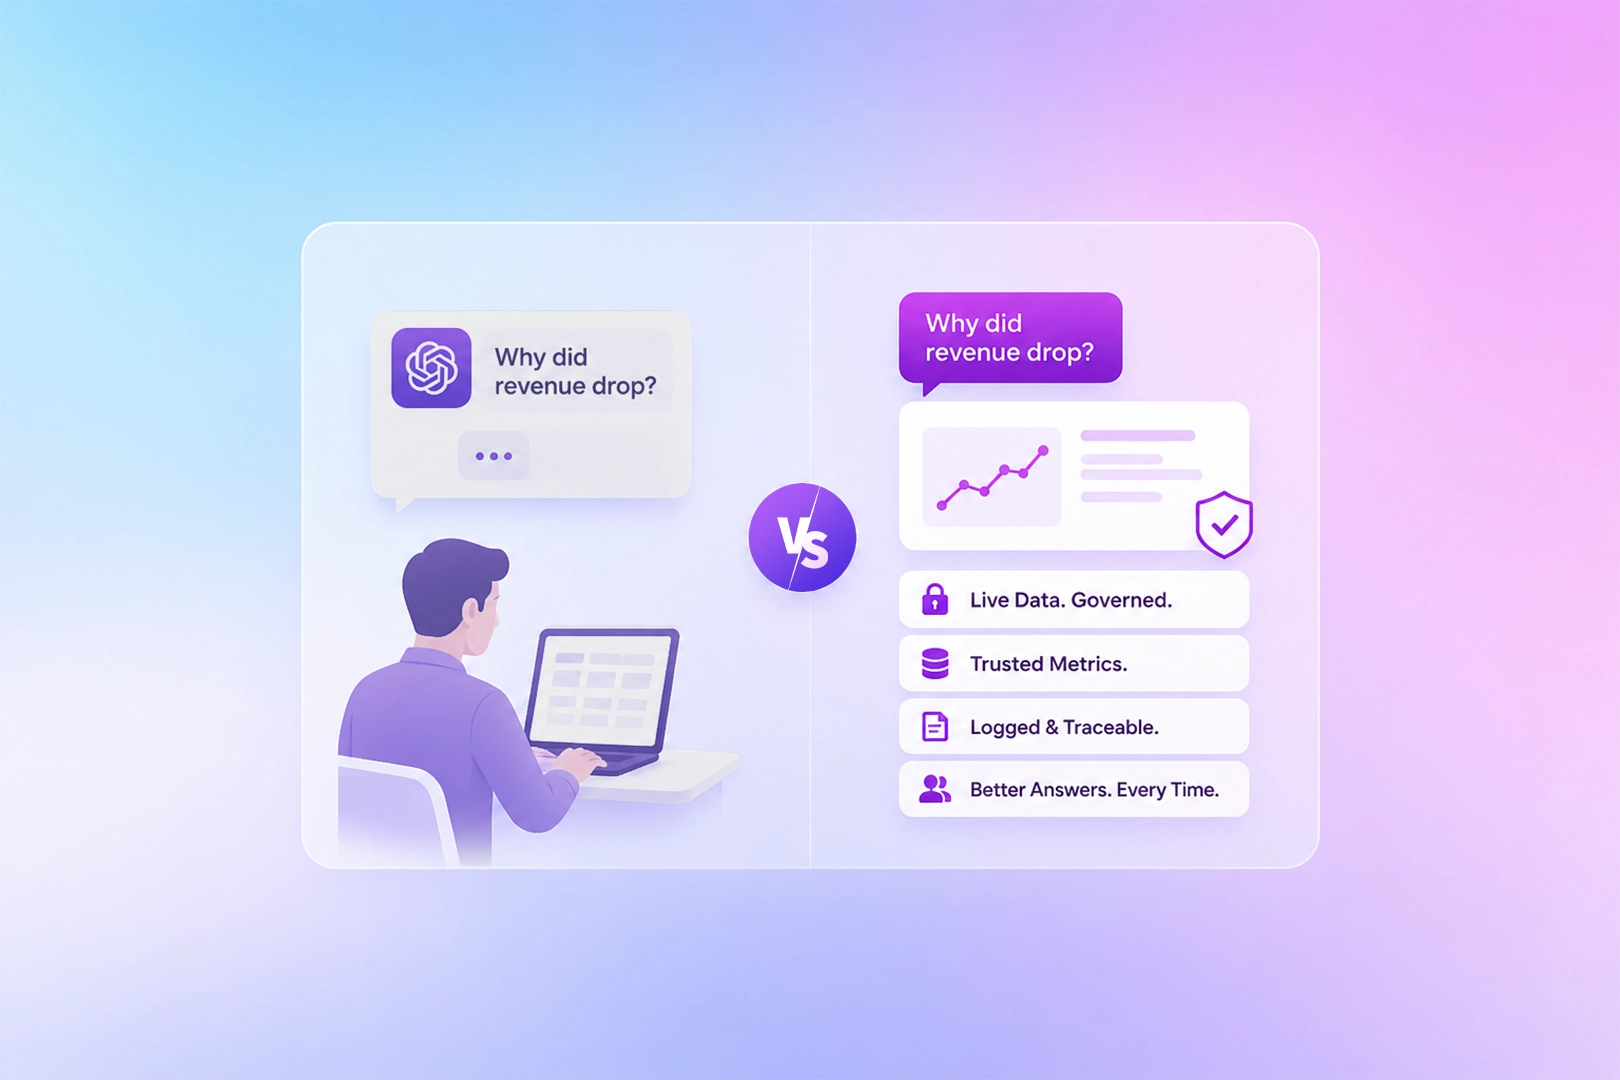
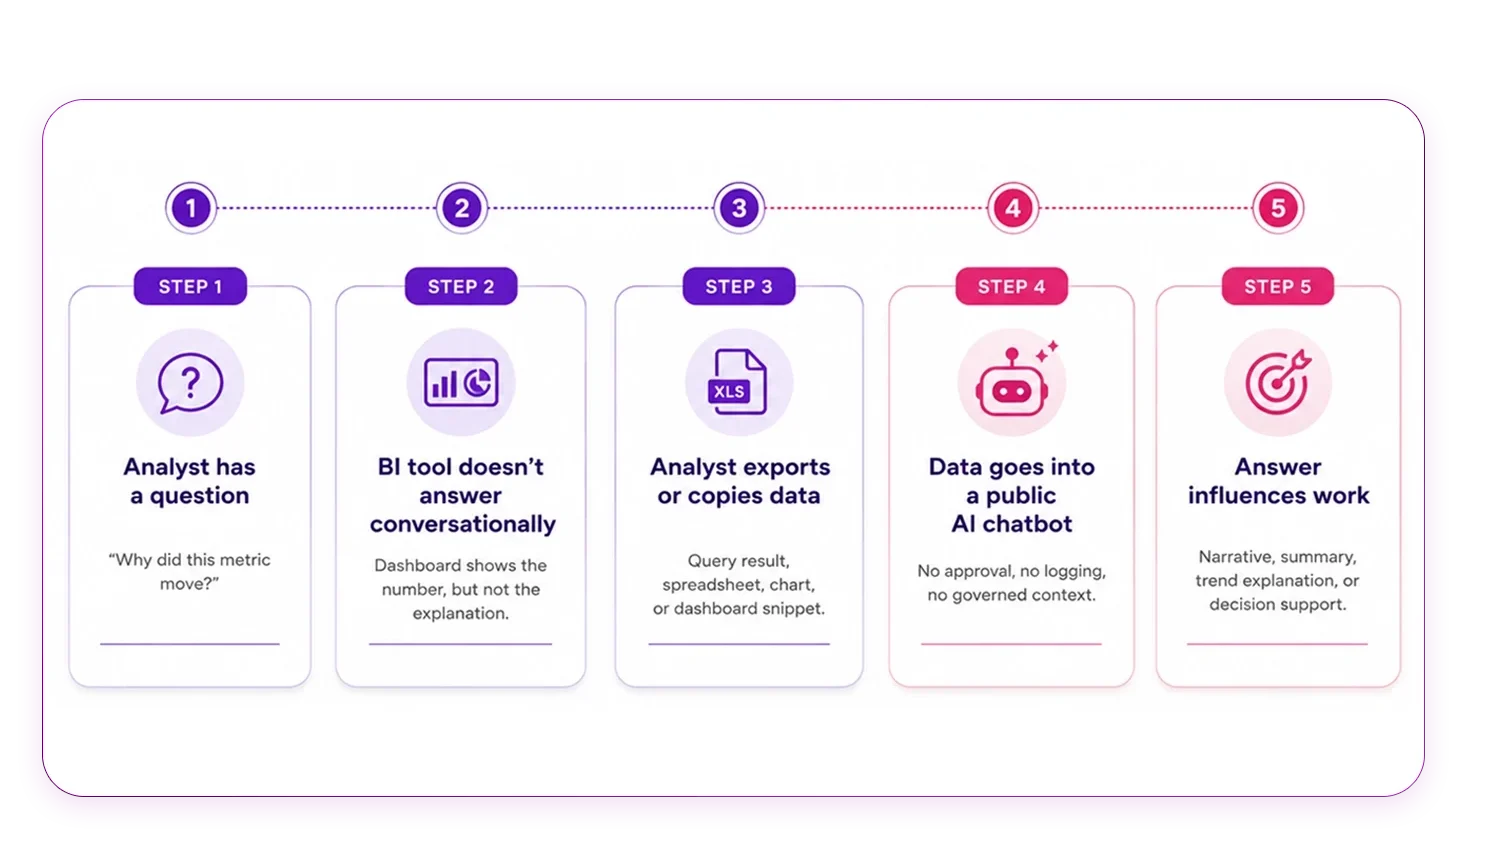
    Somewhere in your organisation this week, an analyst copied query results out of the warehouse, pasted them into a public AI chatbot, and asked it to explain the trend. Nobody approved this. Nobody logged it. The analyst was not being reckless; they were being rational. They had a question, the sanctioned BI stack could not answer it conversationally, and a free tool in a browser tab could. That single act, multiplied across every data-literate employee with a deadline, is the shadow-AI problem, and it is the direct descendant of every shadow-IT wave that came before it.

    Shadow AI is a demand signal wearing a risk costume

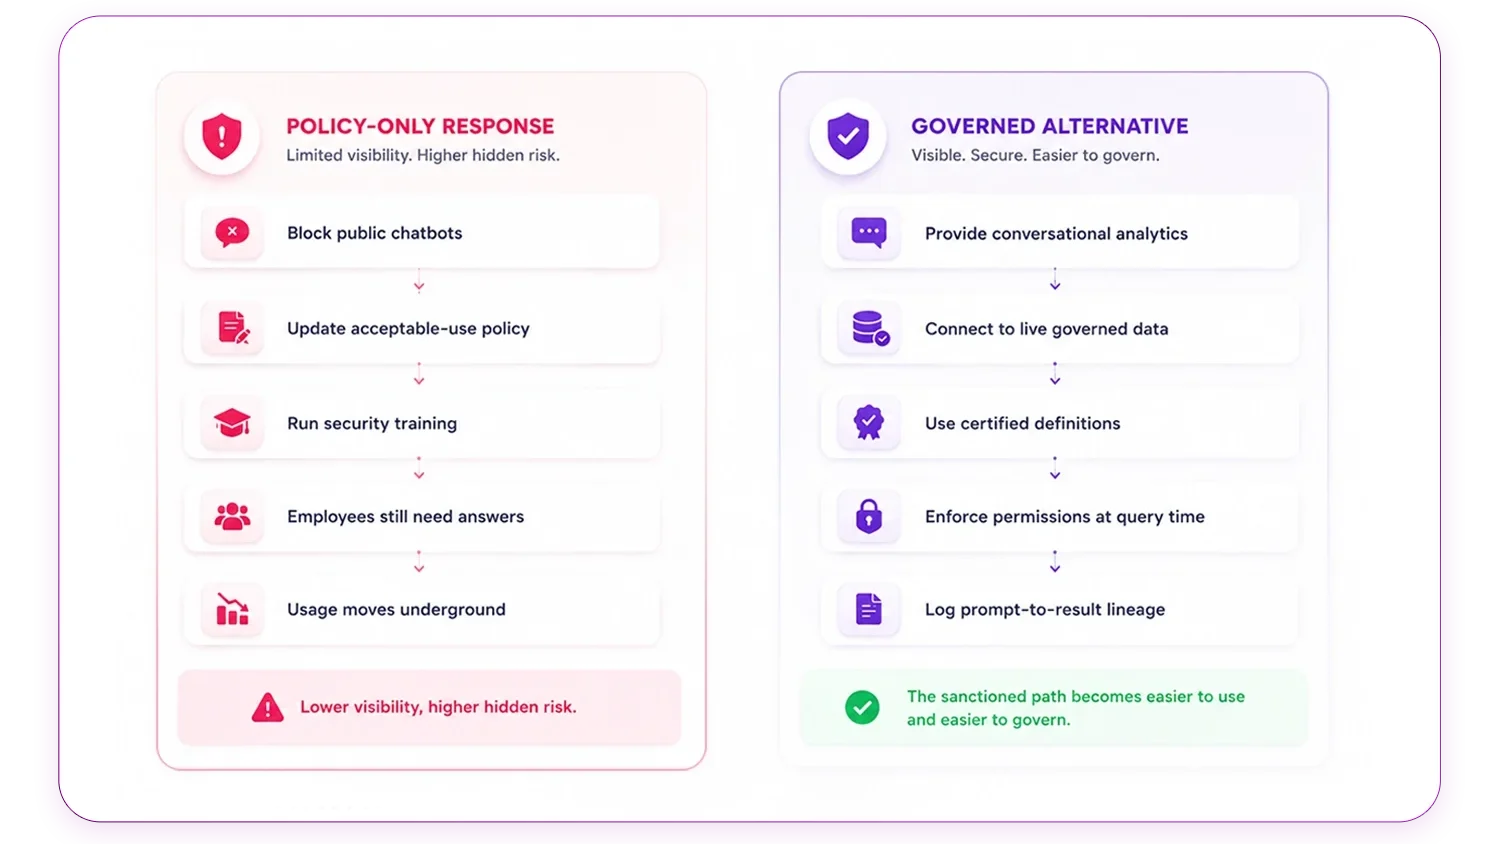
    The instinctive response is enforcement: block the domains, update the acceptable-use policy, remind everyone in the next security training. This treats the behaviour as a discipline problem, and it misreads what is actually happening. Employees route around sanctioned tools when the sanctioned tools fail them, and the failure here is specific. Dashboards answer the questions someone anticipated when the dashboard was built. The questions people actually have, why did this number move, what is different about this cohort, which of these explanations holds up, are conversational and investigative. Public chatbots handle exactly that interaction, so the work flows to them. Shadow AI is what unmet demand for conversational analytics looks like in the wild. The demand is the valuable information. The routing is the problem.

    What the organisation loses on every shadow query

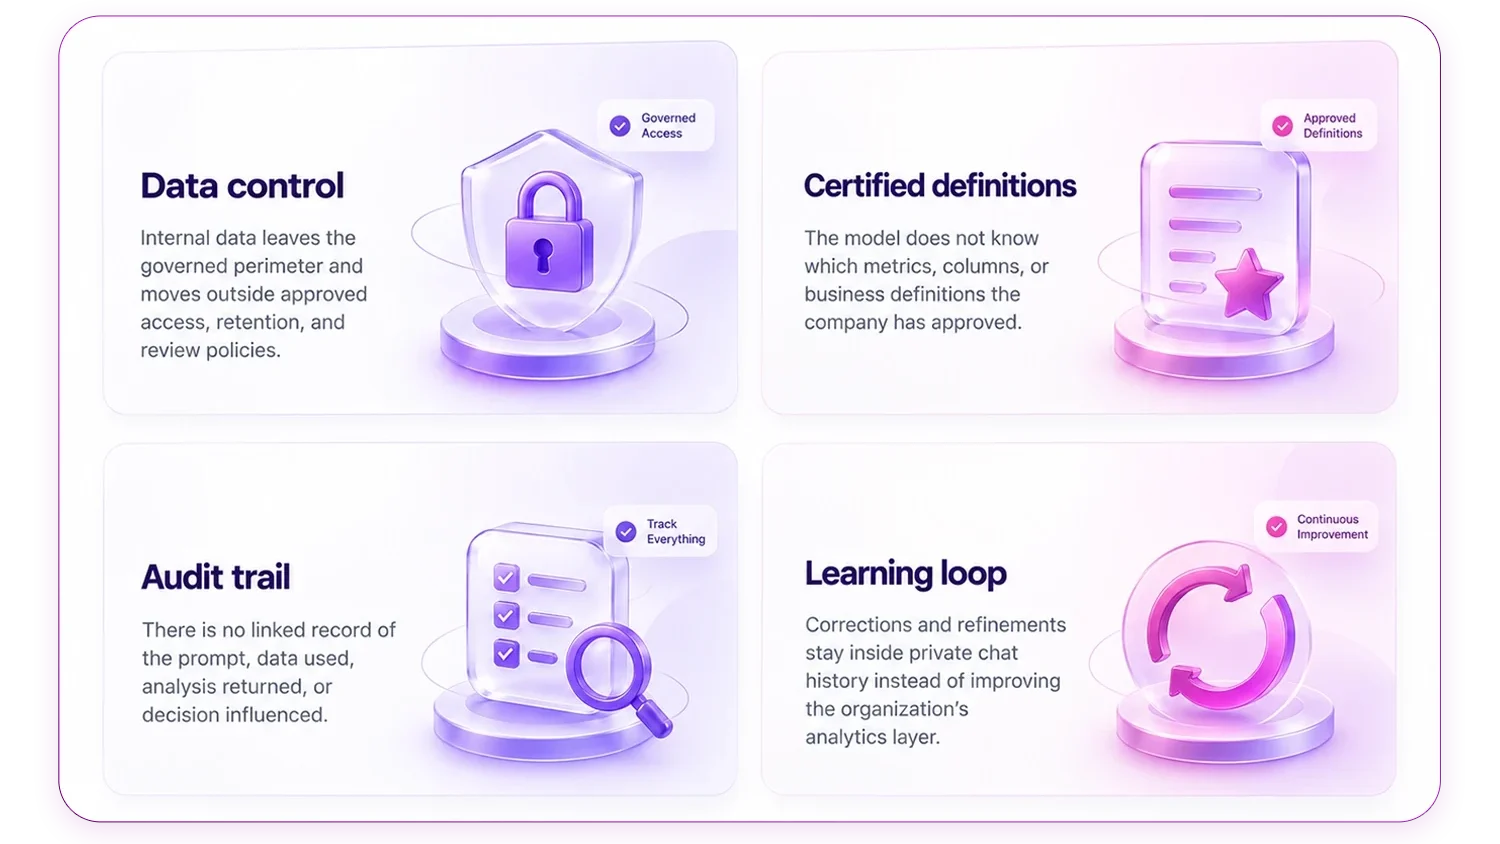
    The obvious loss is data control. Enterprise data pasted into a consumer chatbot has left the governed perimeter, outside the organization’s access controls, retention policies, and, depending on the tool’s terms, potentially into a vendor’s systems under conditions no one reviewed.
    For regulated data, that can constitute a reportable incident on its own. But the quieter losses compound just as badly. The answer the analyst receives is ungrounded: a general-purpose model with no knowledge of the company’s certified metric definitions is guessing at what the columns mean, and its confident narrative may rest on a misreading no one will catch. The interaction is unlogged, so the analysis that later influences a decision has no lineage at all. And the correction loop is severed: when the analyst refines the question or fixes the model’s misunderstanding, that learning evaporates into a private chat history instead of improving anything the organization owns.

    Why prohibition alone has never won this fight

    Shadow IT history is unambiguous on this point. Unsanctioned file sharing was not defeated by blocking consumer storage sites; it ended when enterprises deployed sanctioned tools that were as easy to use. Personal devices were not banished from corporate email; they were brought under management. In every case, the resolution was the same: match the convenience, add the controls. Prohibition without a sanctioned alternative does not stop the behaviour. It selects for the employees most willing to hide it, which makes the risk less visible and therefore worse. An organisation that blocks public chatbots while offering nothing conversational in return has not closed the gap. It has pushed the gap underground.

    The sanctioned path has to win on convenience, not just on policy

    The durable fix is to give analysts a conversational interface that is better than the shadow option on the merits, not merely compliant. Better here has a precise meaning. The sanctioned tool answers in the same conversational register, but against live warehouse data rather than a pasted fragment, so the analyst stops doing the copy-and-paste work at all. Its answers resolve against certified definitions from a semantic layer, so “gross margin” means what finance says it means, which a public chatbot can never know. Permissions are enforced at query time, so the tool is usable on sensitive data instead of being quarantined from it. Every interaction is logged prompt-to-result, so the analysis has lineage. And corrections feed back into the platform’s semantic understanding, so each analyst’s refinement improves the next analyst’s answer instead of vanishing.

    When the governed option clears the convenience bar, usage moves, and it moves measurably. Based on QuaerisAI customer deployments and published materials, one enterprise deployment alongside Power BI produced a 400 percent lift in data interaction: questions that previously went unasked, or went to shadow channels, arriving through a governed interface instead. That is the shadow-AI problem solving itself in the only way it ever durably does, by making the sanctioned path the path of least resistance.

    Treat the shadow queries as your requirements document

    For data leaders, the practical move is to stop reading shadow-AI activity purely as a violation and start reading it as free product research. The questions employees take to public chatbots are a precise map of what the current BI estate cannot do: which investigations people need, which metrics confuse them, where dashboards end and real questions begin. An organisation that answers that map with a governed conversational platform converts its riskiest behaviour into its adoption case. One that answers with policy memos alone will be writing the same memo again next year.

    Frequently asked questions

    What is shadow AI?

    Shadow AI is the use of AI tools, most commonly public chatbots, for work tasks without organisational approval, oversight, or logging. In analytics it typically looks like employees pasting internal data or query results into a consumer AI tool to get explanations, summaries, or analysis the sanctioned BI stack does not provide conversationally.

    Is shadow AI riskier than earlier shadow IT?

    In one important respect, yes. Earlier shadow IT mostly moved files; shadow AI moves data into systems that generate confident analytical claims about it. The organisation is exposed twice: once when the data leaves the governed perimeter, and again when an ungrounded, unlogged answer flows back in and influences a decision. The second exposure is harder to detect because the artefact it produces looks like ordinary analysis.

    Should organisations block public AI chatbots entirely?

    Blocking can be a reasonable interim control for sensitive data, but it is not a solution on its own, because it addresses the routing without addressing the demand. The pattern that has worked across every shadow-IT wave is pairing the control with a sanctioned alternative that matches the convenience of the shadow tool. Policy sets the boundary; the governed alternative is what actually moves the behaviour.

  • The text-to-SQL evaluation checklist: 12 questions to ask before you buy

    The text-to-SQL evaluation checklist: 12 questions to ask before you buy

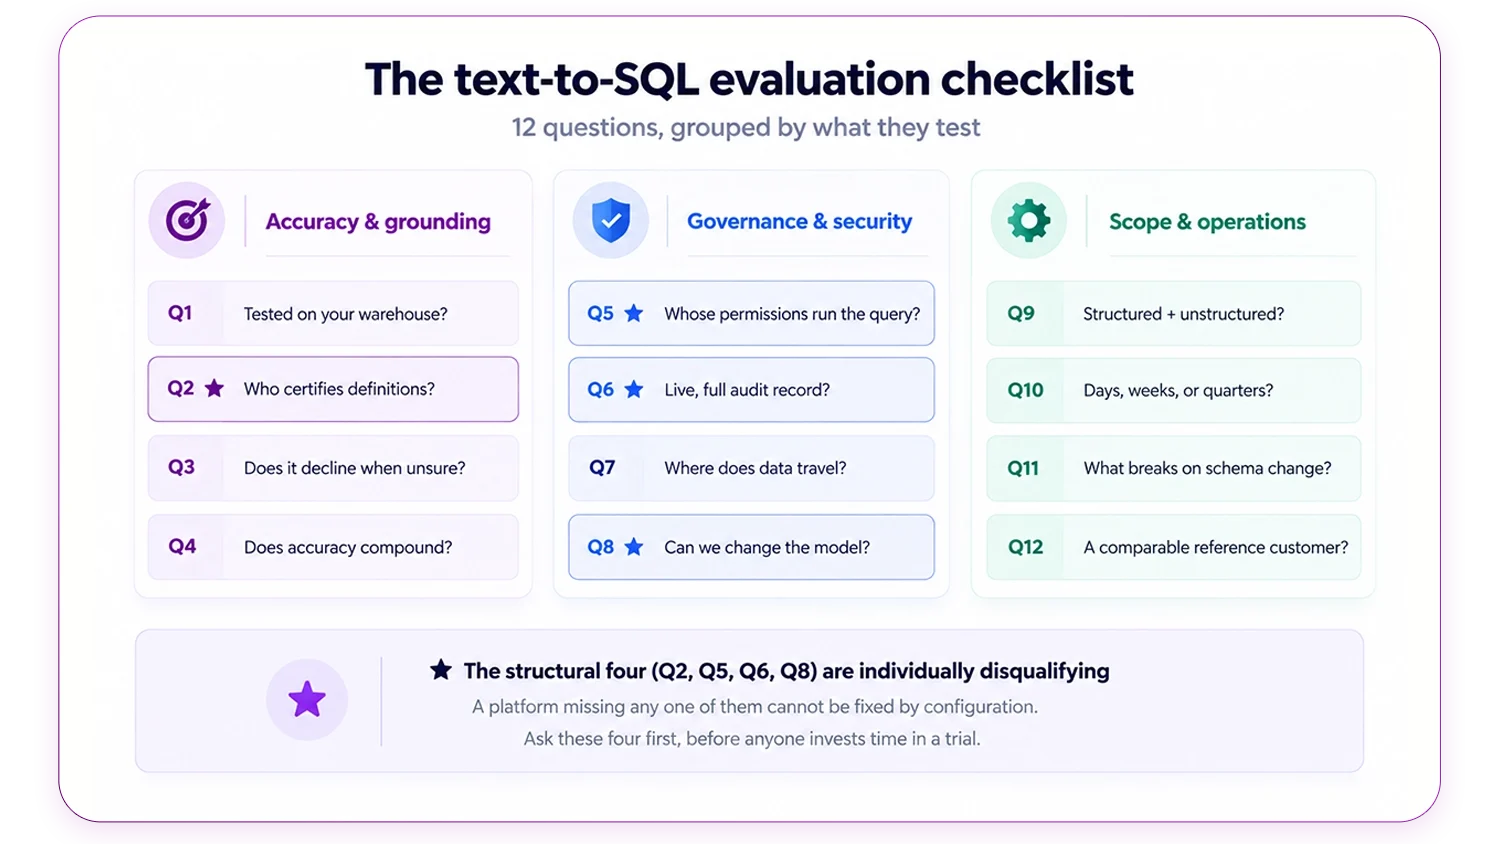
    Buying a text-to-SQL platform is an exercise in seeing past the demo, because every vendor’s demo works. The model generates clean SQL against a tidy schema, the answer appears in seconds, and the room is impressed. The differences that decide whether the platform survives contact with your warehouse, your permissions, and your auditors are invisible in that moment, and they have to be extracted deliberately. The twelve questions below are designed to do the extracting. Each comes with the answer a serious platform should give and the evasion that should end the conversation.

    Accuracy and grounding

    1. Will you run the evaluation on our warehouse, at its full size, before we sign?

    The only accuracy that matters is accuracy on your schema, with your ambiguity and your table count. A confident vendor agrees to a structured trial against your environment using your questions. A vendor who insists the demo environment is representative is telling you their accuracy does not survive scale, whether they know it or not.

    2. Where does the system get its business definitions, and who certifies them?

    The right answer describes a semantic layer: a governed store of metric definitions, blessed tables, and join paths that the business signs off and the model must use. The wrong answer is any version of “the model understands your schema,” because schemas do not contain business meaning, and a system inferring definitions per query will contradict itself across users and phrasings.

    3. What happens when the system does not know what a term means?

    Enterprise-grade behaviour is to ask for clarification or decline, and to record having done so. If the demo never shows the system declining anything, ask to see it. A platform that always produces an answer is a platform that guesses, and guessing is where silently wrong numbers come from.

    4. How does accuracy improve after deployment, and does improvement persist?

    Look for a concrete learning mechanism: analyst corrections that flow into the semantic layer and hold for every subsequent user, which is how QuaerisAI’s Smart Semantic Layer compounds. Be wary of answers that reduce to “the models keep getting better,” because model upgrades do not teach the system your fiscal calendar, and per-user chat memory that evaporates between sessions is not organisational learning.

    Governance and security

    5. Whose permissions does a generated query run under?

    The only acceptable answer is the asker’s, enforced at query time, inherited from your identity provider. Many products connect through a broad service account and filter results in the application layer, an arrangement that leaks the first time the model generates a query nobody anticipated. Ask the vendor to demonstrate two users with different entitlements asking the same question and receiving appropriately different results.

    6. Show us the complete audit record for one query, live.

    Phrased as a demand rather than a question, deliberately. The record should link, as one retrievable chain, the asker and their role, the prompt as typed, the definitions it resolved against, the generated SQL, the tables touched, the model used, and the result. If producing this requires stitching separate logs together or an engineering ticket, the platform has logging, not lineage, and your auditors will notice the difference.

    7. Where does our data travel, and what reaches the model vendor?

    You are listening for a warehouse-native architecture in which queries run where the data lives, with no bulk data movement into the vendor’s environment, and a precise account of what appears in model prompts. Vague reassurance on this question is disqualifying in a regulated industry, because your CISO will ask it with subpoena-grade precision later.

    8. Which language models can power the platform, and can we change our choice?

    Model choice is a compliance and procurement question, not a technical preference. A BYOM architecture lets you select among providers such as Anthropic, OpenAI, Google, and Meta, and switch as your requirements, your regulators, or the model market change. A platform bound to a single model vendor transfers that vendor’s roadmap risk and pricing power directly onto you.

    Scope and operations

    9. Can it answer questions that span structured and unstructured sources?

    A growing share of real business questions joins warehouse data with what lives in documents: contracts, policies, claims files, reports. A platform limited to tables answers half the question and leaves the other half to shadow tools. Ask for a live demonstration of a single query drawing on both, with the same governance applying to each side.

    10. What does deployment actually require, in time and in our people’s hours?

    Get specific: weeks or quarters, and how much semantic modeling must exist before first value. Architectures requiring exhaustive upfront modeling of the warehouse impose a tax measured in months; platforms that start from a certified core and learn outward reach usefulness far sooner. QuaerisAI deployments, based on QuaerisAI published materials, are measured in days rather than quarters, and any vendor should be held to stating their number equally plainly.

    11. What breaks when our warehouse changes?

    Warehouses evolve continuously: new tables, renamed columns, migrated sources. Ask how the platform detects and absorbs schema change, and what the failure looks like when a certified definition points at something that moved. The poor answer is silent breakage discovered by users; the good answer involves detection, flagged definitions, and a governed correction path.

    12. Which of your reference customers looks like us, and can we speak to them?

    Like you means your industry’s regulatory posture, your warehouse scale, and your user population, because text-to-SQL success is environment-dependent in exactly those dimensions. A vendor without a comparable reference is asking you to be the reference, which is a discount conversation, not a list-price one.

    Using the checklist

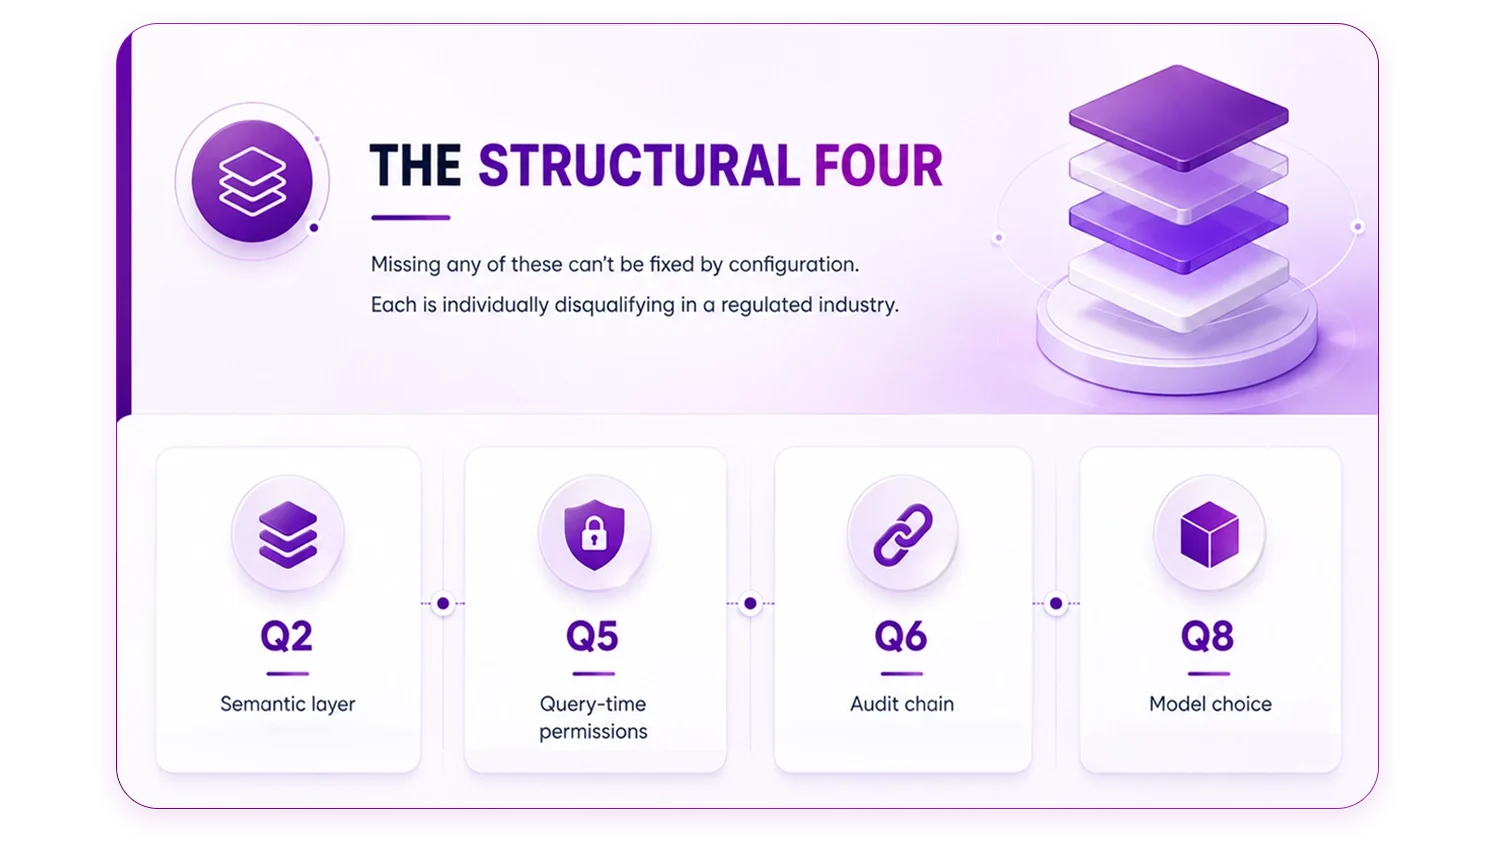
    The twelve questions sort into a simple scoring posture. Questions 2, 5, 6, and 8, the semantic layer, query-time permissions, the audit chain, and model choice, are structural: a platform missing any of them cannot be remediated by configuration, and in a regulated industry each is individually disqualifying.

    The remainder calibrate cost, speed, and fit. Run the structural four in the first vendor meeting, before anyone invests in a trial, and reserve the trial itself for question 1, executed on your warehouse with a gold-standard question set your analysts have answered independently. An evaluation run in this order costs days and routinely saves the year that a failed deployment consumes.

    Frequently asked questions

    Should this checklist apply to tools bundled with our warehouse or BI suite?

    Yes, with particular attention to questions 5, 6, and 8. Bundled tools inherit an assumption of safety from the platform they ship with, but bundling does not create query-time permission enforcement or prompt-level lineage where the architecture lacks it, and bundled tools are usually bound to their vendor’s model choices by design. The checklist is vendor-neutral precisely because the gaps are not.

    How long should a proper evaluation take?

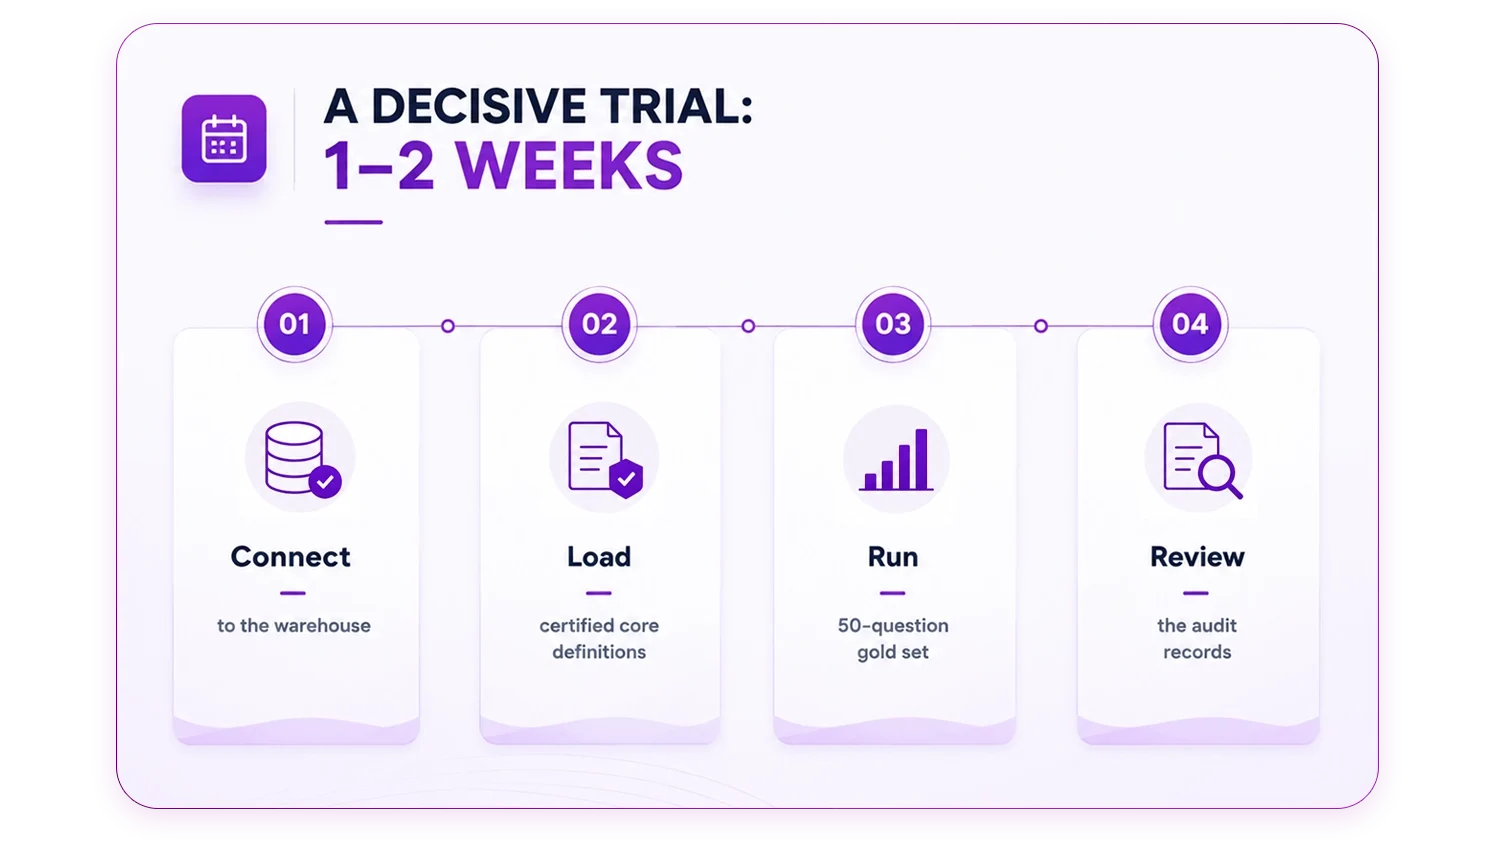
    With the structural questions asked up front, a decisive trial fits in one to two weeks: connect to the warehouse, load the certified core definitions, run a fifty-question gold-standard set, and review the audit records. Evaluations that stretch to months usually indicate either an architecture requiring heavy upfront modeling or an evaluation with no defined pass criteria, and both are findings in themselves.

    Who should be in the room for the vendor sessions?

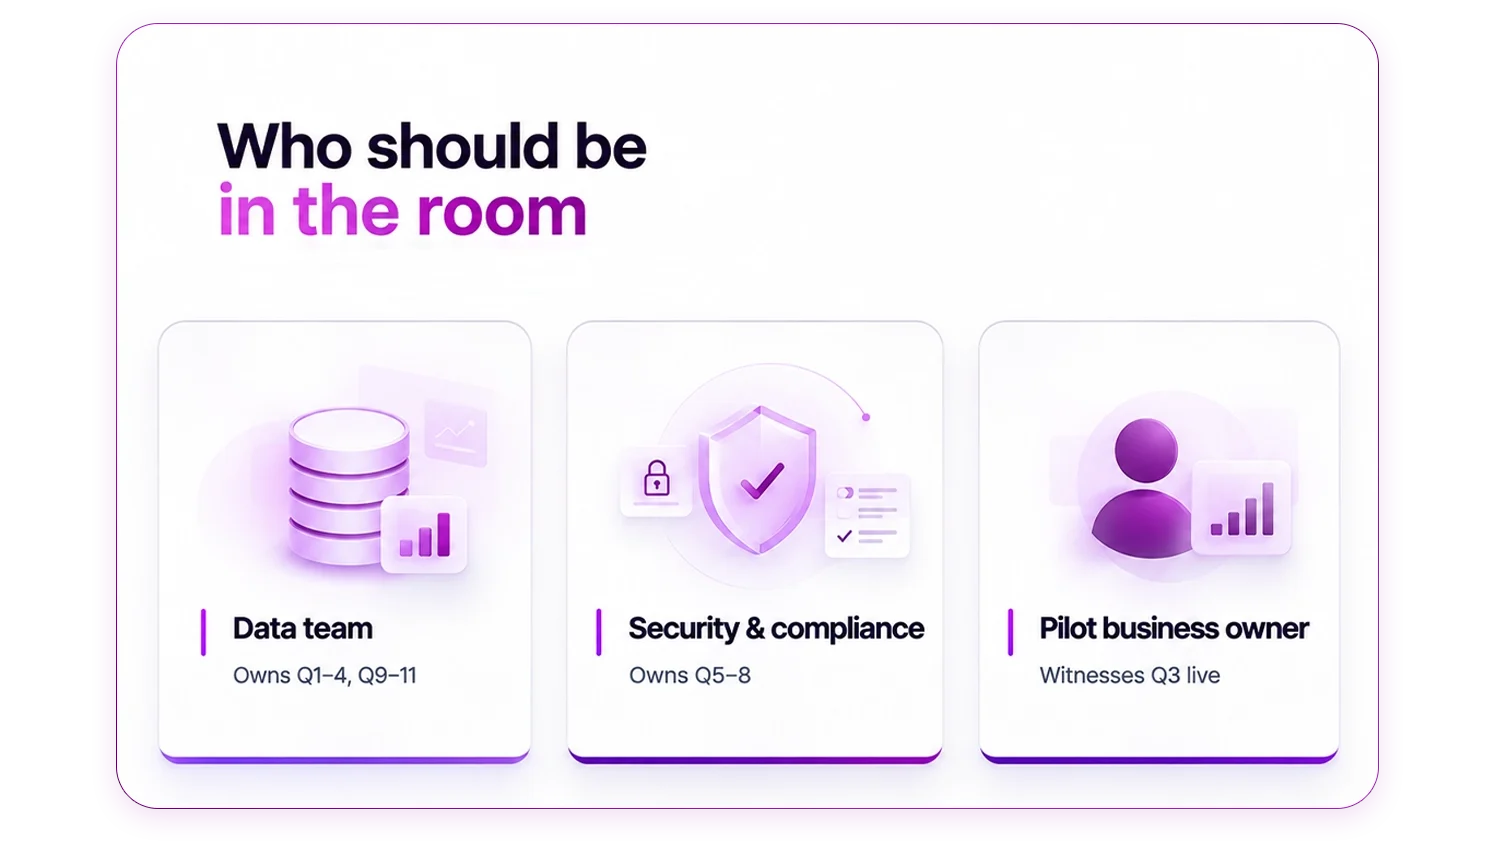
    The data team owns questions 1 through 4 and 9 through 11; security and compliance own 5 through 8; and the business owner of the pilot domain should witness question 3, because how a system behaves at the edge of its knowledge is the clearest single preview of whether their team will trust it.

  • The hidden cost of bad SQL: how to measure text-to-SQL accuracy

    The hidden cost of bad SQL: how to measure text-to-SQL accuracy

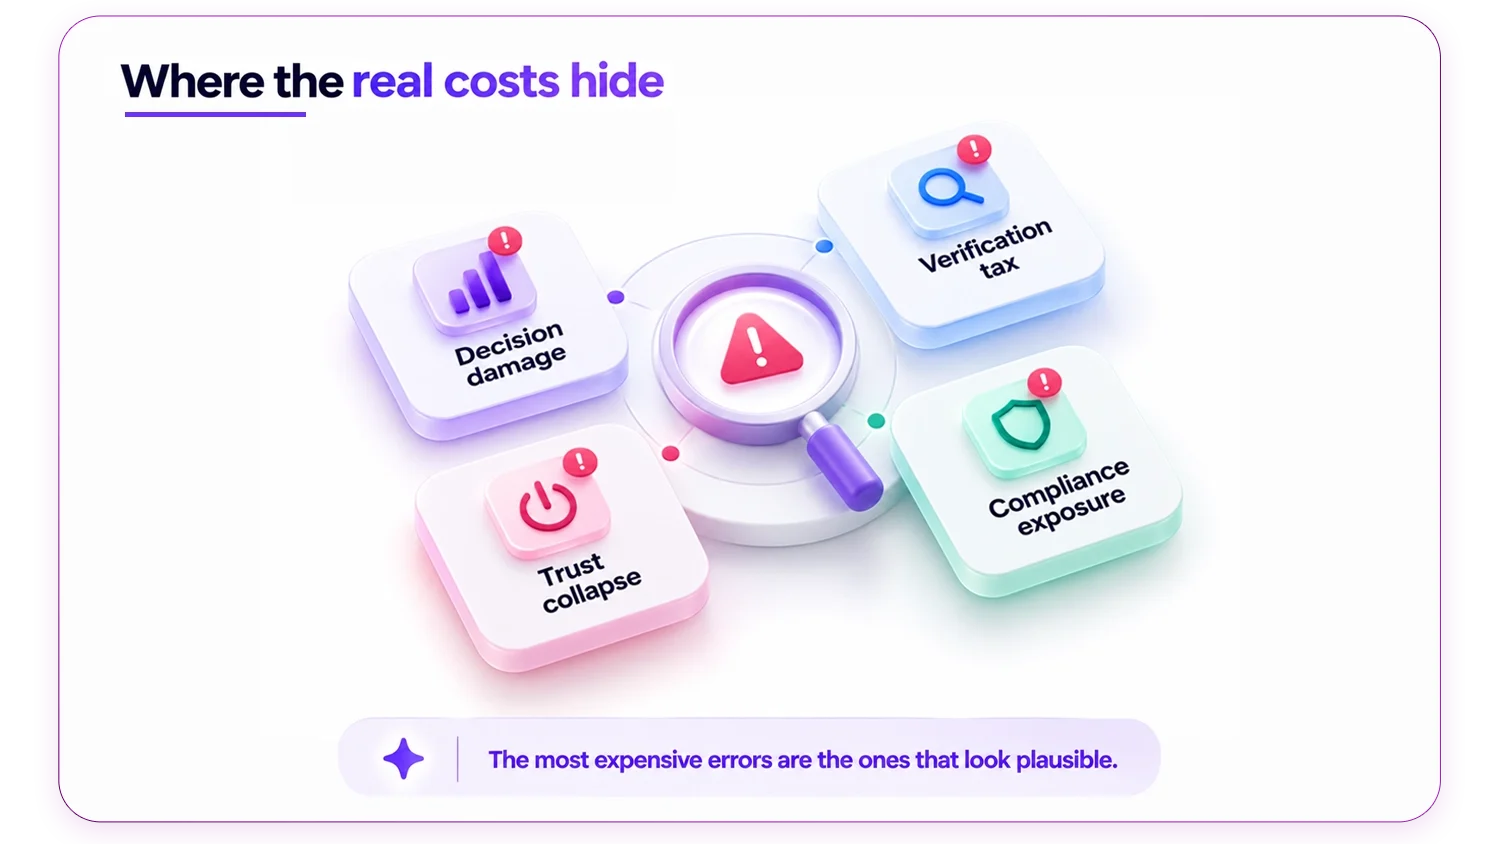
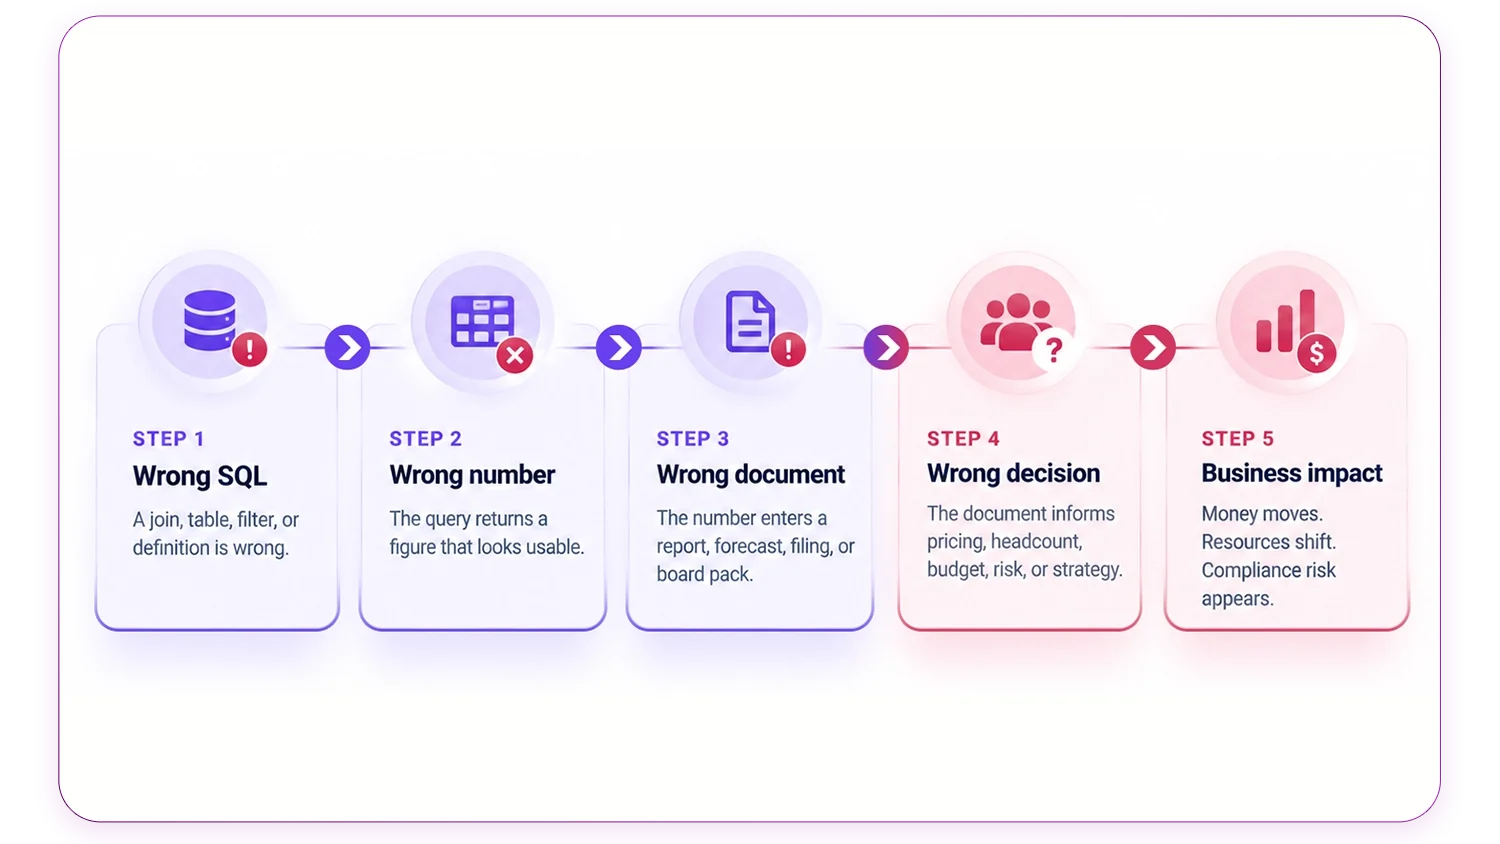
    A wrong query is never just a wrong query. By the time an incorrect SQL statement has done its work, it has produced a number, the number has entered a document, the document has informed a decision, and the decision has moved money, headcount, or strategy. The cost of bad SQL is the cost of everything downstream of it, which is why “our text-to-SQL system is about 90 percent accurate” is one of the least informative sentences in enterprise software. Ninety percent of what, measured how, and what did the other ten percent cost? This piece breaks down where the real costs hide, and then lays out how to measure accuracy in a way that actually predicts them.

    The cost ledger: four entries, mostly invisible

    The first entry is decision damage, and it is the largest and least measurable. A silently wrong figure that shapes a pricing decision, a forecast, or a resource allocation does its damage long before anyone traces it back to a misgenerated join. Because the harm surfaces far from the cause, it is almost never charged to the analytics system that produced it, which is precisely why it is the hidden cost rather than the visible one.

    The second entry is verification tax. Once an organisation has caught a system being confidently wrong even once, rational users begin re-verifying its answers, and re-verification means an analyst reproducing the work by hand. At that point the system has negative productivity: it costs everything it cost before, plus the tool. The third entry is trust collapse, which behaves like a cliff rather than a slope. Users do not discount a system proportionally to its error rate; past a threshold of burned trust, they abandon it entirely, and adoption, the metric the entire business case rested on, goes to zero. The fourth entry, specific to regulated industries, is compliance exposure: a wrong number in a filing or an examined report is not an inefficiency but an incident, with remediation costs that dwarf any tooling budget.

    Why the vendor’s accuracy number does not predict your costs

    Accuracy claims usually derive from public benchmarks, and public benchmarks systematically overstate production performance for reasons covered at length elsewhere: small clean schemas, unambiguous questions, none of your business rules. But there is a subtler measurement problem inside the metric itself. Most benchmarks score execution accuracy, whether the query returns the expected result on the test database. In production, what matters is semantic accuracy: whether the query means what the asker meant, using the definitions the business certifies. A query can execute perfectly and be semantically wrong, computing revenue from the uncertified table or ignoring the fiscal calendar. Execution accuracy on someone else’s database is, at best, weakly correlated with semantic accuracy on yours, and semantic accuracy is the one your cost ledger responds to.

    Measuring accuracy so the number means something

    A meaningful accuracy programme has three components, and all three run on your own warehouse with your own questions. The first is a gold-standard evaluation set: fifty to one hundred real questions drawn from actual analyst traffic, each paired with a correct answer that your own analysts have independently produced and a business owner has signed off.

    The set must be deliberately adversarial in proportion to reality, including questions that depend on unwritten business rules, questions that route through your ambiguous tables, questions requiring multi-step joins, and a handful of questions that are unanswerable from the data, where the correct behaviour is to decline or ask for clarification rather than to produce something. Scoring the system’s willingness to say “I cannot answer this” is not a soft extra. Refusal behaviour is where silent errors go to die.

    The second component is graded scoring rather than pass-fail. A useful rubric distinguishes at least four outcomes: correct, correct but suboptimally derived, wrong in a way a reviewer would catch, and wrong in a way that reads as plausible. That last category deserves its own tracked rate, because plausible-wrong is the failure mode that generates decision damage, and a system’s overall accuracy can improve while its plausible-wrong rate holds steady, which is a deterioration disguised as progress. The third component is continuous measurement in production. Evaluation sets go stale as the warehouse and the business evolve, so the programme should sample live queries on a fixed cadence, have analysts verify the sample, and trend the results. A platform with a complete prompt-level audit trail makes this nearly free, because every answer already carries its SQL and sources; verification becomes a reading exercise. A platform without one makes the sampling itself a reconstruction project, which is a strong signal about the platform.

    Accuracy measurement is also the improvement engine

    The measurement programme pays a second dividend when the platform can learn from it. In a static system, a failed evaluation item is a data point; the same failure recurs next quarter. In a system with an auto-learning semantic layer, each verified failure becomes a correction that persists: the misresolved term gets a certified definition, the wrong join path gets superseded, and the error class closes rather than recurring. This converts the evaluation set from a report card into a training curriculum, and it is the mechanism by which accuracy compounds over time instead of plateauing. Based on QuaerisAI customer deployments and published materials, this compounding loop underpins outcomes like the reduction of a standard audit engagement from 170 hours to 70 hours, a 59 percent reduction: the hours come out only when answers can be trusted at first pass, and first-pass trust is built by exactly this cycle of measurement and permanent correction.

    The one-line summary for the business case

    The cost of bad SQL is dominated by errors nobody catches, so the only accuracy number worth putting in a business case is one measured on your warehouse, scored for semantic correctness against certified definitions, with the plausible-wrong rate reported separately. Any vendor figure that arrives without that provenance is a marketing input, not a planning input.

    Frequently asked questions

    What accuracy rate is good enough for production?

    There is no universal threshold, because tolerance depends on the blast radius of an error and on whether errors are catchable. A system feeding exploratory analysis with full SQL visibility can tolerate more than one feeding regulated reporting. The practical standard is a plausible-wrong rate low enough that your sampling programme rarely finds one, combined with an audit trail that makes every answer verifiable when it matters. Verifiability buys more safety than any accuracy decimal.

    How often should the evaluation set be refreshed?

    Quarterly is a sound default, with two triggers for off-cycle refreshes: material warehouse changes such as migrations or new source systems, and any change to the platform’s underlying model. Refresh means retiring questions that no longer reflect real traffic and adding new ones drawn from recent live queries, keeping the set adversarial in the same proportions.

    Who should own text-to-SQL accuracy measurement?

    The data team runs the mechanics, but sign-off on gold-standard answers belongs to the business owners of the metrics, because semantic accuracy is defined by their certified definitions. A useful pattern is a standing quarterly review where the data team presents the sampled accuracy trend and the plausible-wrong rate to the same governance forum that owns metric definitions, closing the loop between measurement and certification.

  • Why text-to-SQL accuracy collapses at 50+ tables (and how the semantic layer fixes it)

    Why text-to-SQL accuracy collapses at 50+ tables (and how the semantic layer fixes it)

    Somewhere between the proof of concept and the production warehouse, text-to-SQL systems hit a wall, and teams that have lived through it describe the same experience: the tool that answered flawlessly against a curated 15-table demo begins missing badly once it faces the real estate of several hundred tables. The decline is not gradual or graceful. Practitioners consistently report it arriving as a collapse, and the threshold where it becomes undeniable tends to sit surprisingly low, often at a scale of tens of tables rather than thousands. Understanding why the collapse happens at that scale explains what actually fixes it, and why the fix is architectural rather than a matter of waiting for smarter models.

    The collapse is combinatorial, not linear

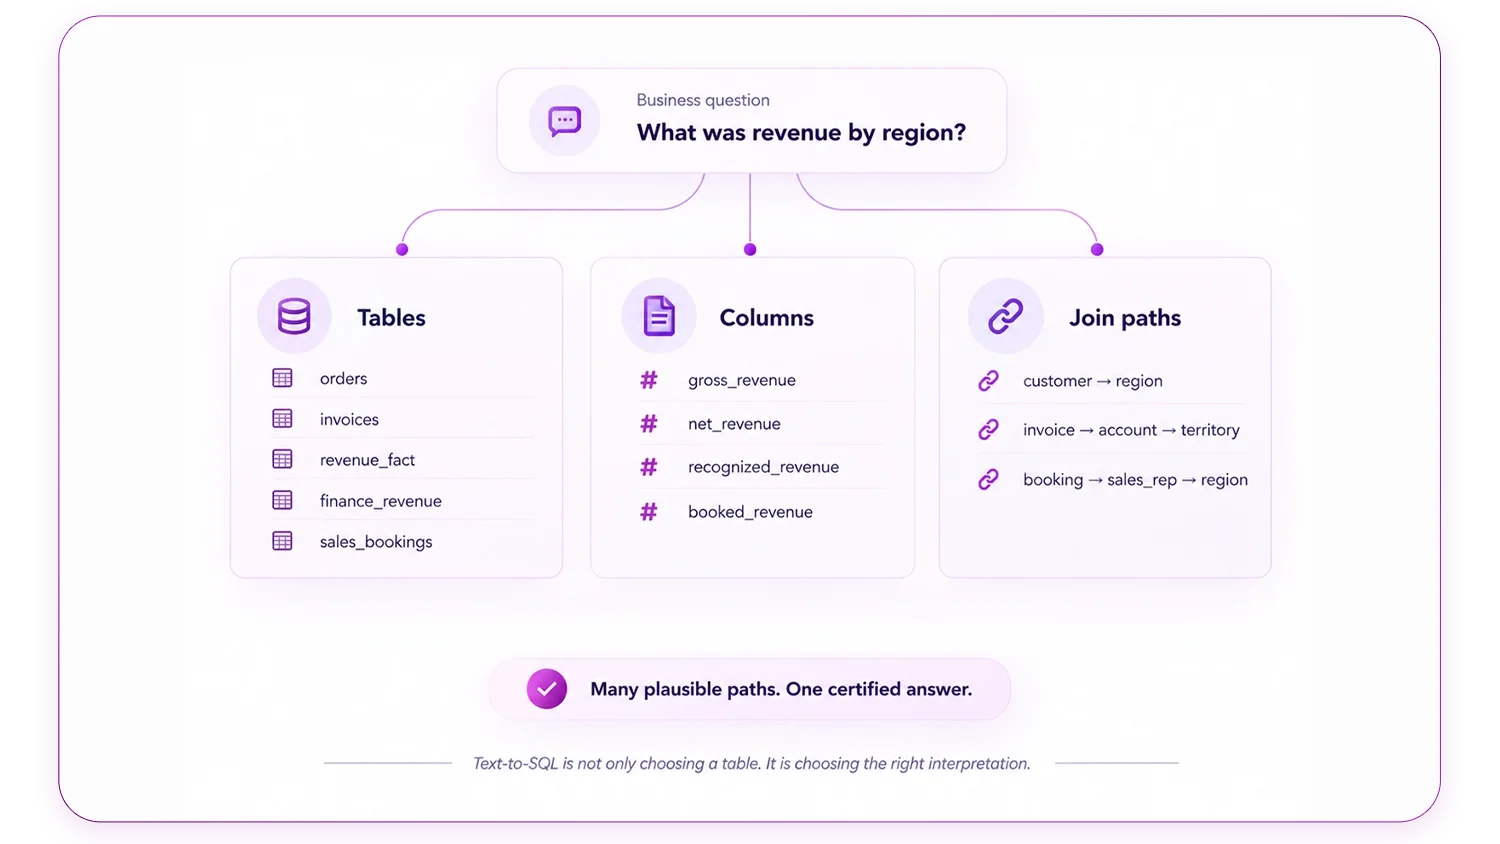
    The intuition that a warehouse with ten times the tables is ten times as hard is wrong, and the reason is that query generation is a search problem. To answer a question, the system must select the right tables, the right columns within them, and the right join paths between them. Each of those choices multiplies against the others. With a dozen tables, the space of plausible interpretations of a question is small, and the correct one is usually the obvious one. With a hundred tables, a single business question can map to dozens of superficially reasonable table combinations, joined along multiple superficially reasonable paths, and only one combination reflects how the business actually computes the metric. The search space grows combinatorially while the model’s basis for choosing, names and schema structure, stays as thin as it ever was.

    Real warehouses actively mislead the search

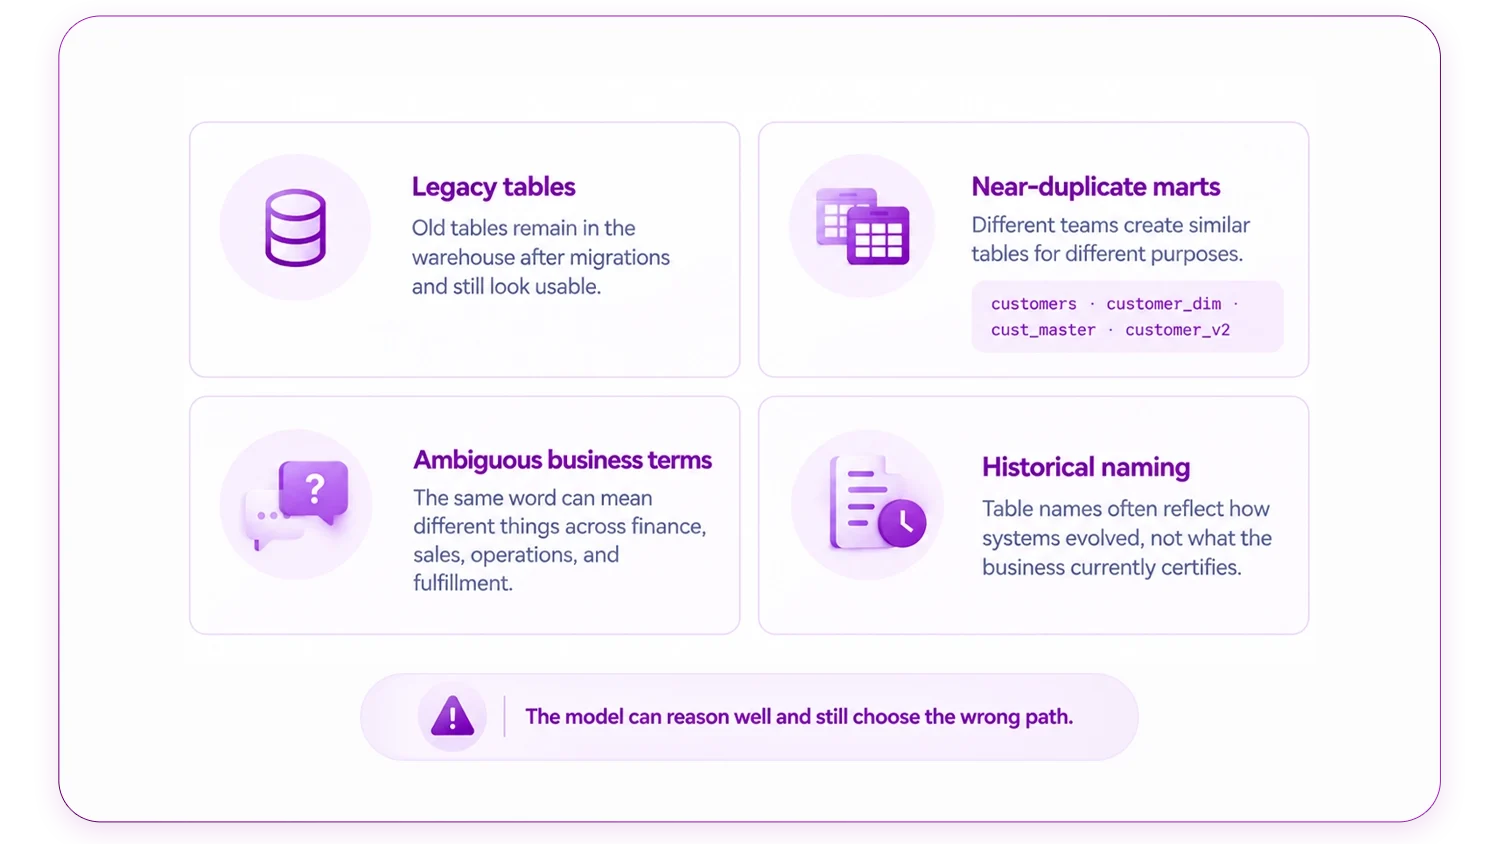
    Scale alone would be manageable if enterprise schemas were honest, but they are not, through no fault of anyone. Warehouses accumulate. Migrations leave behind superseded tables that still hold data. Teams build near-duplicate marts of the same entities for their own purposes, so customers exists alongside customer_dim, cust_master, and a v2 of one of them, and only institutional memory knows which is certified. Naming stops encoding meaning and starts encoding history. Semantic ambiguity compounds it: orders in the fulfilment schema and orders in the finance schema are different grains of different truths. To a model reasoning from the schema, every one of these artefacts is a live, plausible candidate. The model is not failing to reason. It is reasoning correctly over a landscape where most of the well-marked paths lead somewhere wrong.

    Context limits make it worse, and context alone cannot fix it

    There is also a mechanical constraint. A schema of hundreds of tables with their columns, types, and relationships is a large object, and systems must choose what portion of it to show the model for a given question. Retrieve too narrowly and the correct table may never be in view; retrieve broadly and the model wades through hundreds of distractors, where the misleading candidates above sit alongside the right ones with equal prominence. Long-context models relax the mechanical limit but not the underlying problem, because the problem was never fitting the schema into the window. It was that the schema does not contain the information that distinguishes the certified path from the plausible one. Showing the model more of an ambiguous map does not make the map less ambiguous.

    What the semantic layer changes: from search to lookup

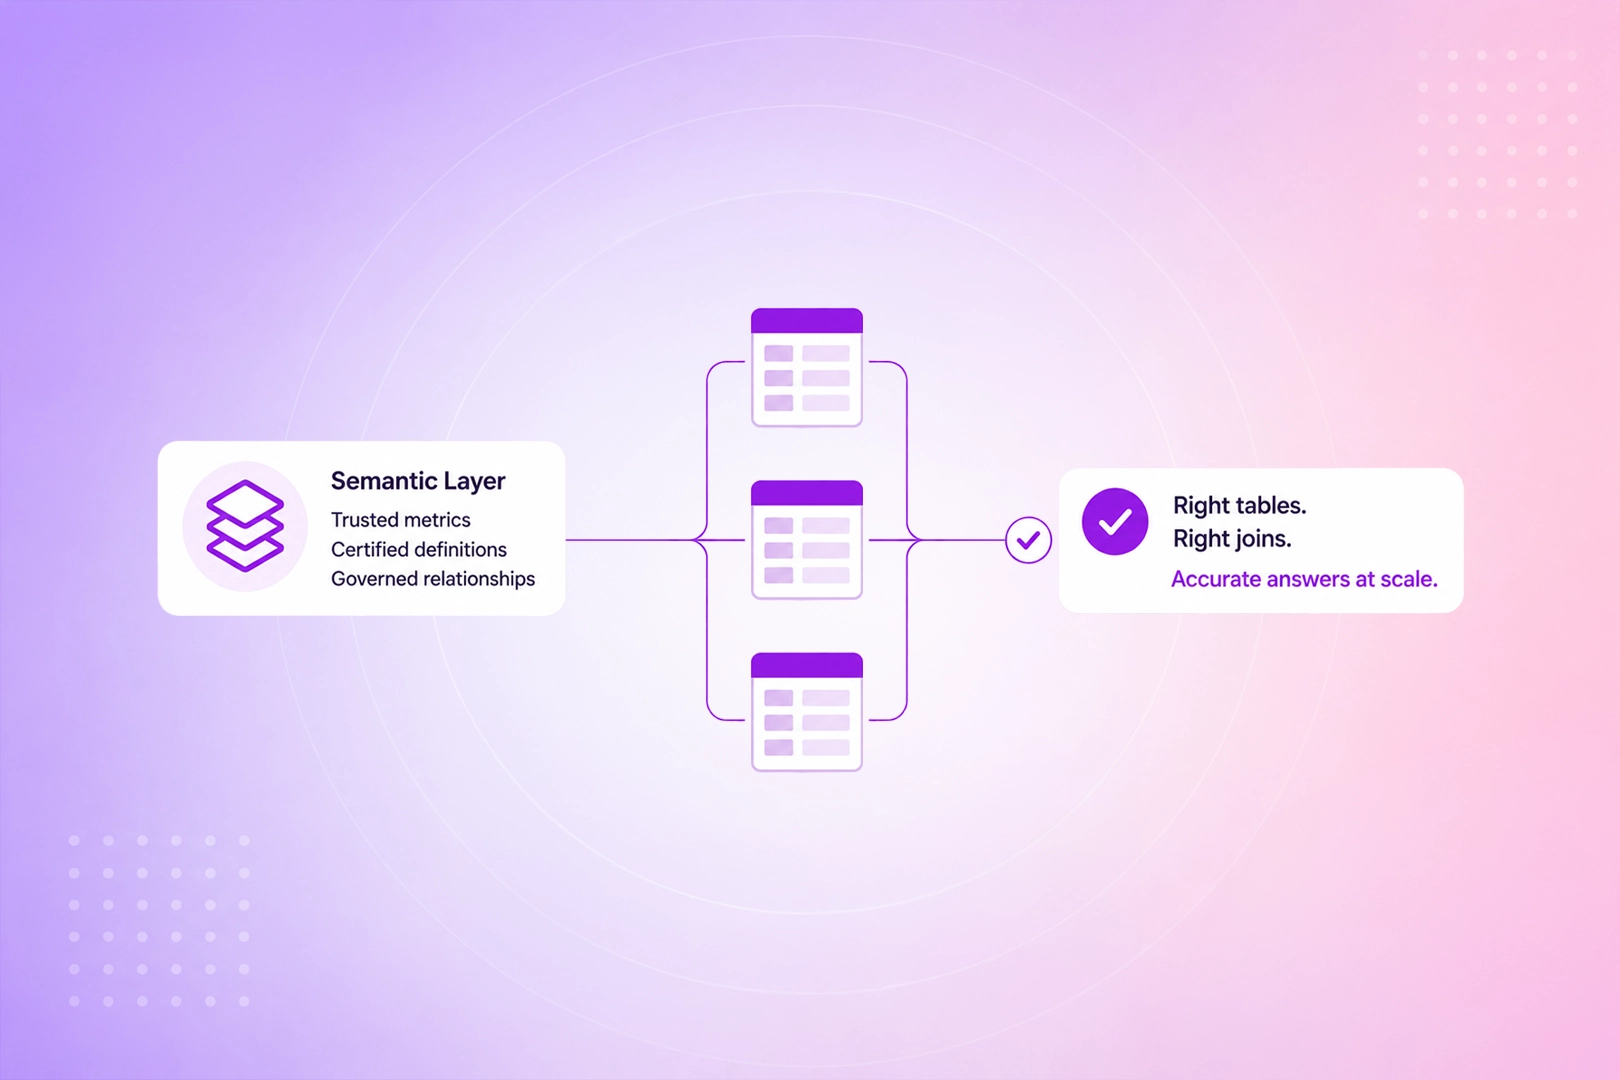
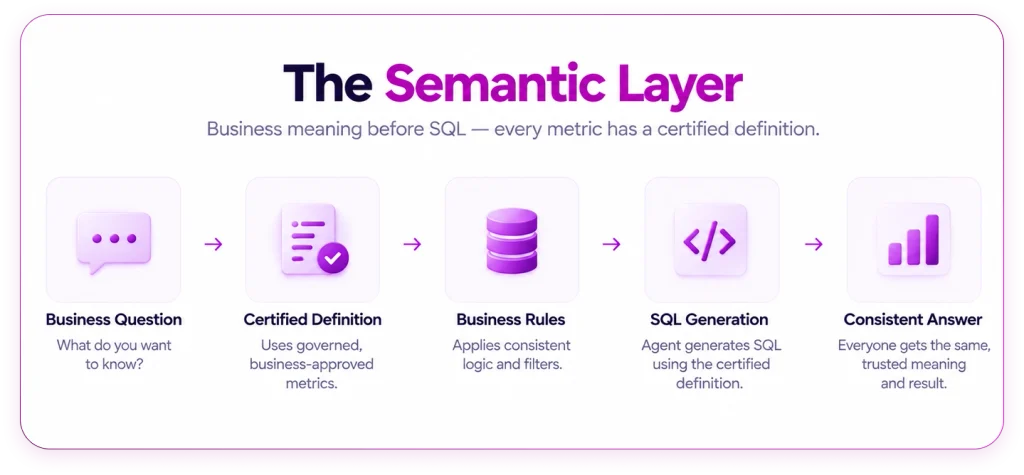
    The semantic layer fixes the collapse by removing the search. Instead of asking the model to rediscover, per query, which of four customer tables is real and how revenue joins to region, the semantic layer holds those resolutions as certified facts: this metric is computed from these columns in these tables along these join paths, as approved by the business. The model’s job contracts from navigating the full combinatorial space to composing an answer from pre-resolved, governed components. The distractor tables never enter the candidate set, because candidacy is now defined by certification rather than by name similarity. This is why the approach scales where schema-prompting does not: the ambiguity that grows combinatorially with warehouse size is exactly the part the semantic layer eliminates, so warehouse growth stops degrading answer quality.

    The traditional objection is maintenance: manually authored semantic models are themselves a large project, and they drift as the warehouse evolves, which is how metric definitions rot. This is the specific problem QuaerisAI’s Smart Semantic Layer is built to address. The layer learns from interaction: when an analyst corrects a resolution or refines how a question maps to data, the correction persists as part of the layer, so coverage compounds with use instead of decaying with time. The maintenance burden that made semantic layers a tax becomes the byproduct of people simply using the system.

    What this means for evaluation

    The practical lesson for buyers is that a text-to-SQL evaluation conducted on a small clean schema measures nothing about production behaviour. The demo scale sits below the collapse threshold by design. A meaningful evaluation runs on your own warehouse at its real size, includes questions whose correct answers route through your ambiguous regions, near-duplicate tables, legacy artefacts, and multi-hop joins, and checks whether the platform resolves them through governed definitions or through guesswork. Systems that pass at that scale do so because their architecture removed the combinatorial problem. Based on QuaerisAI customer deployments and published materials, that is the architecture standing behind adoption rates of 30 to 60 percent: sustained enterprise adoption is only possible when accuracy survives contact with the full warehouse.

    Frequently asked questions

    Is 50 tables a hard threshold?

    No. It is a useful shorthand for the scale at which practitioners commonly report the failure becoming obvious, but the true driver is ambiguity rather than the table count itself. A pristine 80-table schema with unambiguous naming may behave well; a 40-table schema with three overlapping customer marts and legacy artefacts may already be inside the collapse. Table count correlates with ambiguity in real warehouses, which is why the shorthand holds in practice.

    Do retrieval techniques over the schema solve this without a semantic layer?

    They mitigate the mechanical part, choosing which schema fragments to show the model, and are worth having. They do not solve the core problem, because retrieval selects candidates by relevance signals like name similarity, and in a real warehouse the misleading candidates are relevant by exactly those signals. Distinguishing the certified table from its plausible twins requires governed knowledge, which is what a semantic layer is.

    How much semantic modeling is needed before the system is usable?

    Far less than full-warehouse coverage. Question traffic in most organisations concentrates heavily on a modest set of core metrics and entities, so certifying the definitions behind that core covers the bulk of real usage. With an auto-learning layer like QuaerisAI’s, coverage then extends organically along the paths people actually query, rather than requiring the whole estate to be modeled up front.

  • Why your CFO will ask about AI lineage before they ask about AI accuracy

    Why your CFO will ask about AI lineage before they ask about AI accuracy

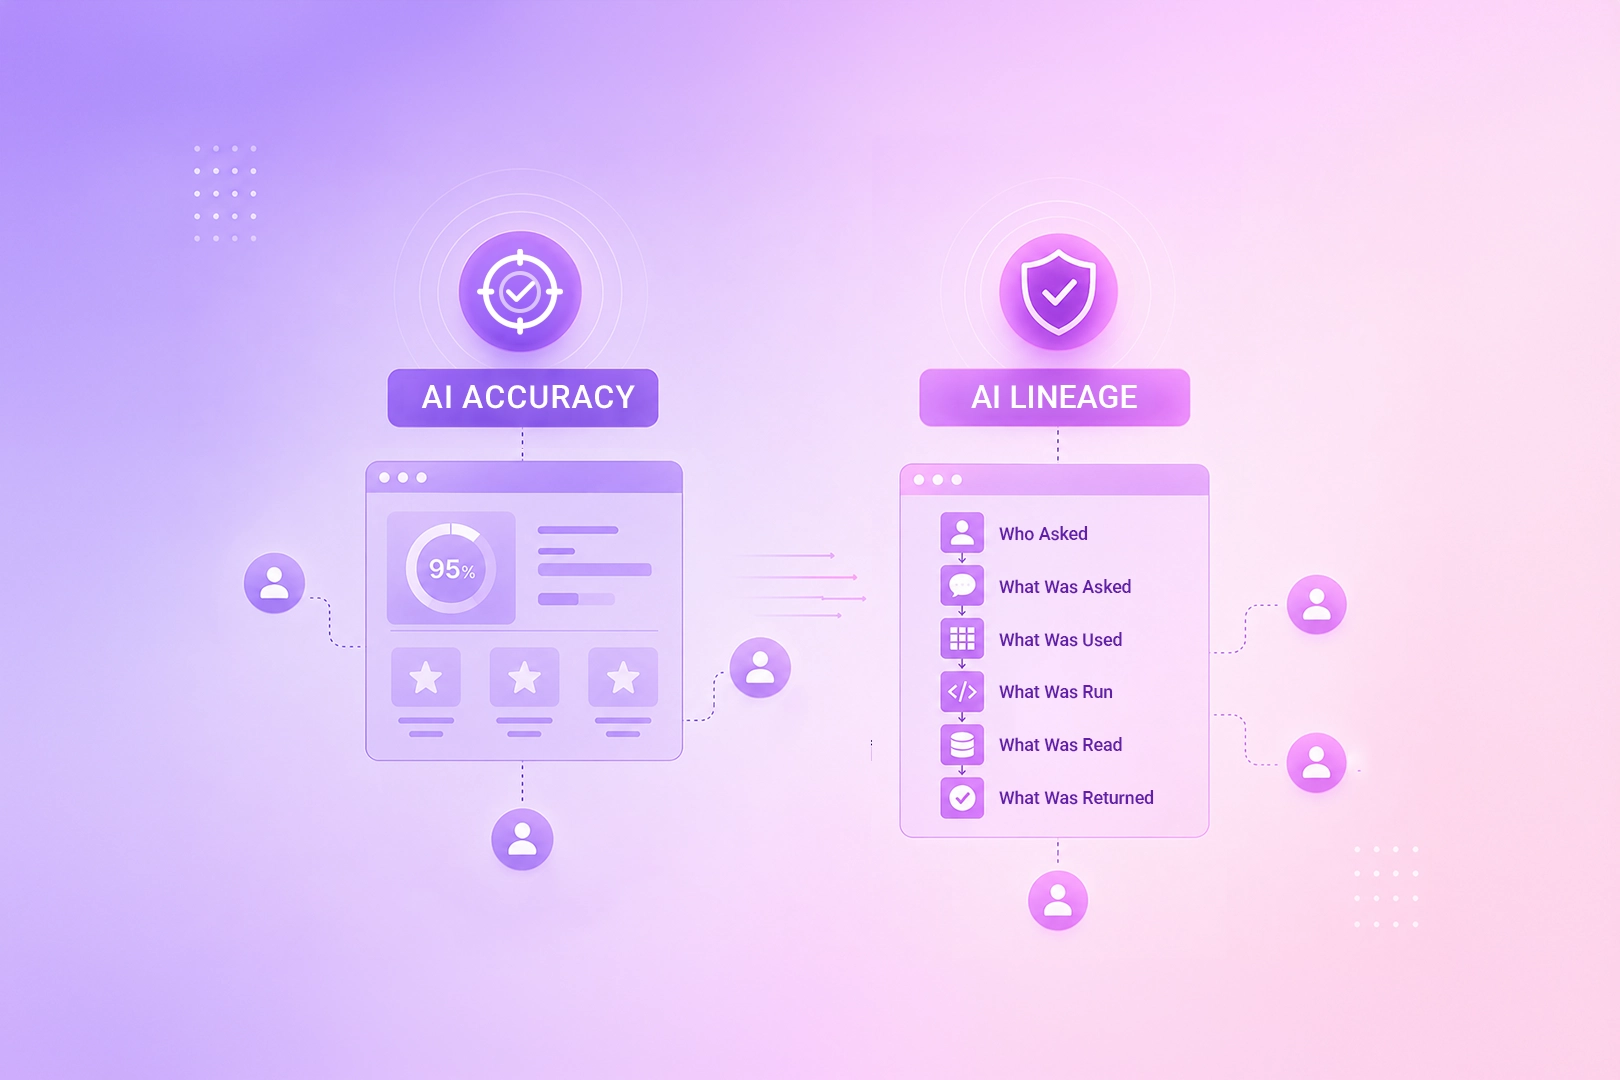
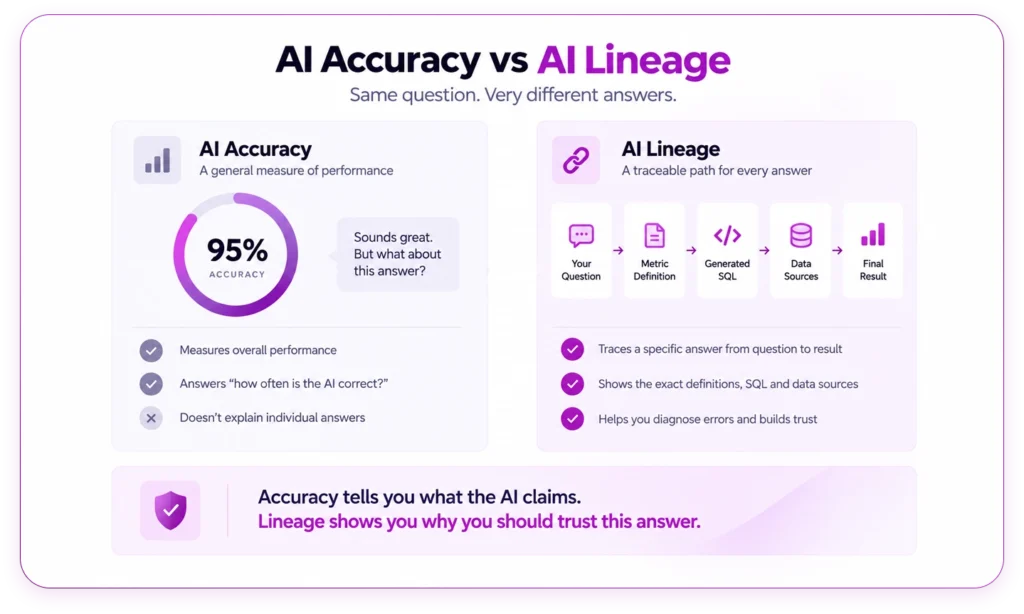
    Accuracy is the wrong first question about enterprise AI, and finance leaders are the first to figure this out. Not because accuracy is unimportant, but because accuracy is a claim, and CFOs are professionally trained to distrust claims they cannot verify. A vendor asserting 95 percent accuracy is telling the CFO nothing actionable. A vendor showing exactly how any individual answer was produced, from the question asked to the data read to the number returned, is telling the CFO something they can build a control around. The first is marketing. The second is lineage.

    Finance runs on traceability, not on averages

    Consider how a finance organisation already treats numbers. No controller accepts a figure into the close because the person who produced it is usually right. Every material number must tie back: to a ledger entry, to a reconciliation, to a documented source. The entire apparatus of financial control, from journal entry approval to SOX testing, is built on the principle that a number’s origin must be demonstrable, not merely trusted. Auditability is not a feature of financial reporting. It is the substance of it.

    An AI agent that produces analysis for finance is entering that apparatus, and the apparatus does not bend for new technology. When an agent’s output feeds a forecast, a close package, or a board deck, the CFO’s question is the same question finance asks of every number: show me where this came from. An aggregate accuracy statistic cannot answer it. The statistic says the system is right most of the time. The CFO needs to know whether it was right this time, and the only way to know is to trace this specific answer back through this specific chain.

    Accuracy without lineage is unverifiable, lineage makes accuracy testable

    Here is the asymmetry that puts lineage first. An accurate system with no lineage gives you correct answers you cannot prove are correct, which in a regulated finance context is nearly as unusable as wrong answers. A system with full lineage gives you something better than a promise: it gives you the means of verification. When every answer carries its question, its resolved metric definitions, its generated SQL, and its source tables, then accuracy stops being a vendor claim and becomes a property your own team can test, continuously, on your own data.

    Lineage is also what makes errors survivable. Every analytical system, human or machine, produces occasional wrong answers. In a lineage-complete system, a wrong answer is diagnosable: the reviewer finds the step where the chain went wrong, whether a misresolved definition or a flawed join, and the fix improves every subsequent answer. In a lineage-free system, a wrong answer is just a mystery that erodes trust, and there is nothing to fix because there is nothing to inspect. CFOs understand this instinctively, because it is exactly why finance documents its own work.

    The CFO is answerable for the number, so the CFO sets the bar

    There is a structural reason this question lands on the CFO’s desk with particular weight. When a figure reaches investors, the board, or a regulator, the CFO is personally accountable for it. Certification regimes in financial reporting attach executive names to reported numbers. An executive who signs numbers does not get to say the AI produced them. So before any AI-assisted analysis gets near external reporting, the CFO will require the same evidentiary standard applied to everything else in the reporting chain: complete, reviewable, retained documentation of origin. That standard has a name in this context, and it is lineage.

    The practical consequence for anyone selecting an analytics platform is that the finance organisation’s requirements will arrive whether or not they were in the original evaluation. Teams that select on demo quality and accuracy claims alone often discover the lineage requirement at the worst moment, when a number is already in circulation and someone senior asks for its provenance. Teams that select for lineage from the start never have that meeting.

    What to be able to show when the question comes

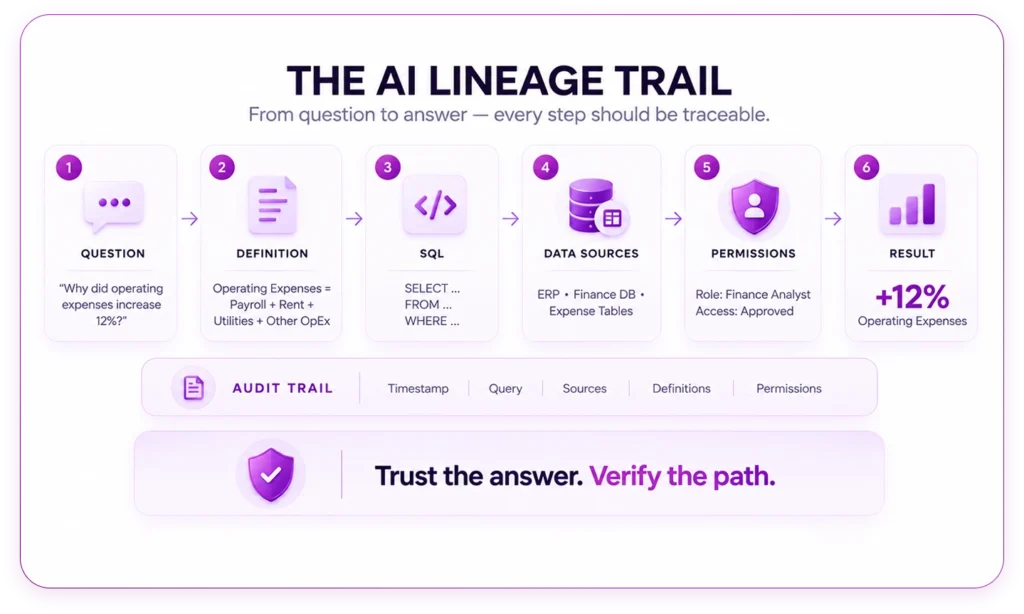
    The test is concrete. Take any single answer the platform has produced and demonstrate, from stored records rather than reconstruction, five things: who asked the question and under what permissions, the exact question asked, the certified definitions the question resolved against, the SQL executed and the tables it read, and the result returned. A platform built for governed agentic analytics produces this chain automatically on every query. Based on QuaerisAI customer deployments and published materials, this is the operating model behind results like a reduction from 170 hours to 70 hours on a standard audit engagement: when every answer arrives with its own evidence, the verification work that consumes senior hours collapses, because the proof was generated with the answer.

    Accuracy will always matter. But accuracy is what the system claims about itself, and lineage is what lets your CFO check. In finance, the checkable thing wins every time.

    Frequently asked questions

    What does AI lineage mean in analytics?

    AI lineage is the complete, recorded chain from a user’s question to the system’s answer: the identity and permissions of the asker, the question as phrased, the metric definitions it was resolved against, the query the system generated, the data sources that query read, the model that produced the reasoning, and the returned result. Data lineage traces where data came from. AI lineage extends the trace through the reasoning and generation steps as well.

    Is high accuracy enough for AI in financial reporting workflows?

    No. Financial reporting standards require that material numbers be supportable with documentation, not merely correct. An accurate answer with no reconstructible origin fails that test, because there is no evidence to review. In practice, lineage is the entry requirement and accuracy is what lineage lets you continuously verify.

    How should a finance team evaluate lineage in a vendor demo?

    Ask the vendor to pull the full record for one specific past query, live, without preparation. The record should show the asker, the prompt, the resolved definitions, the generated SQL, the tables touched, and the result, as one linked chain retrieved from storage. If producing it requires stitching together separate logs or engineering effort, the platform does not have lineage. It has logs.

  • The four pillars of Governed Agentic Analytics: audit, semantic, agentic, BYOM

    The four pillars of Governed Agentic Analytics: audit, semantic, agentic, BYOM

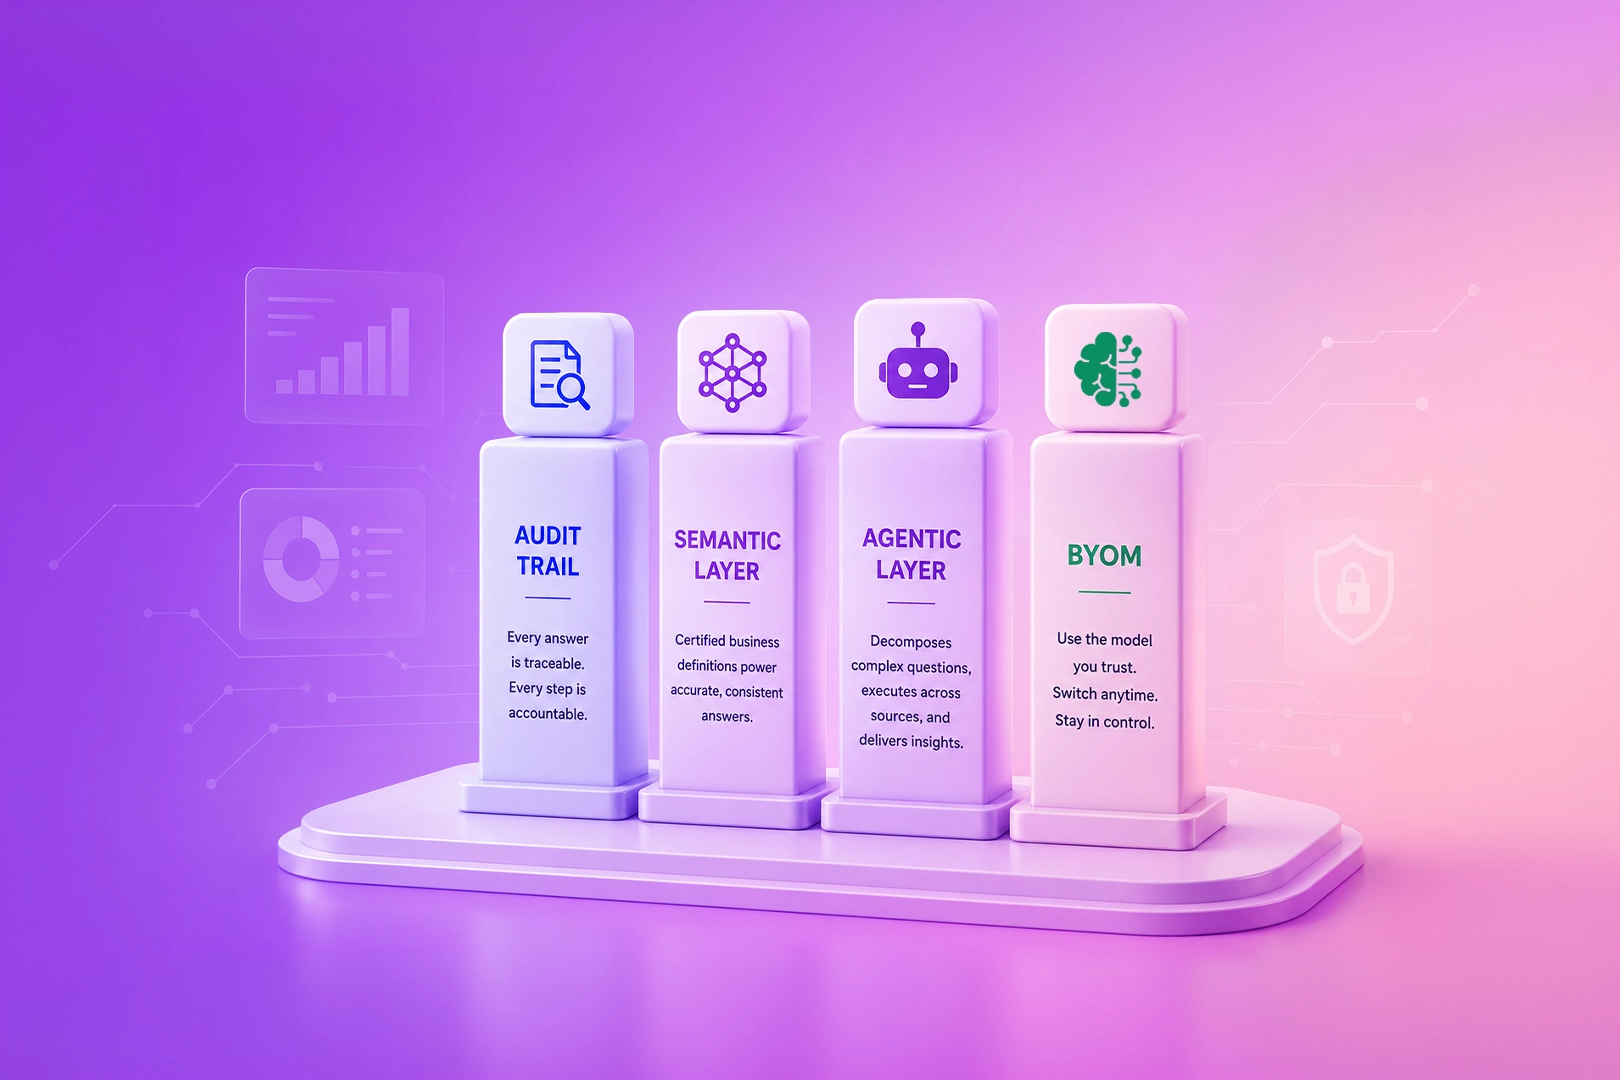
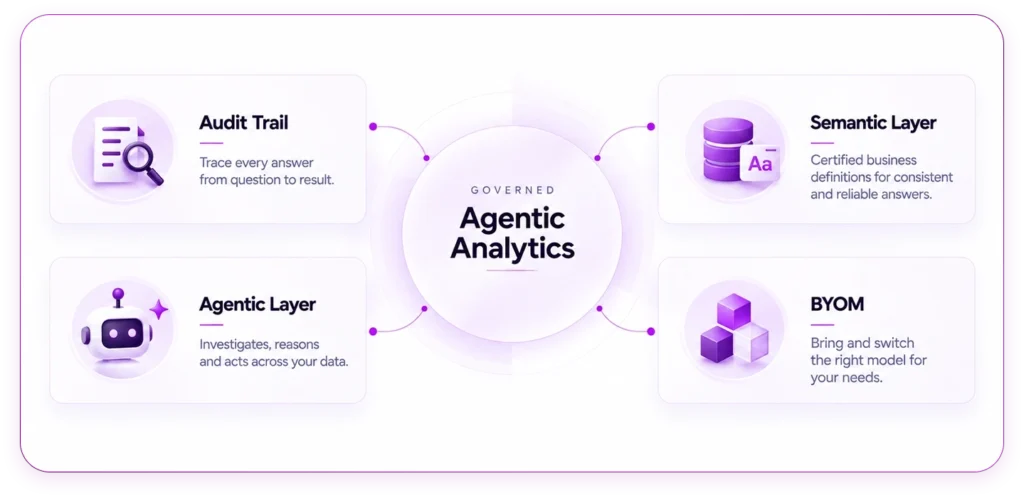
    Four capabilities separate a governed agentic platform from a chatbot bolted onto a warehouse. Remove any one of them and the structure fails in a specific, predictable way. This piece defines each pillar, explains what breaks without it, and shows how the four reinforce one another when they are built as one system rather than assembled from separate tools.

    Pillar one: the audit trail

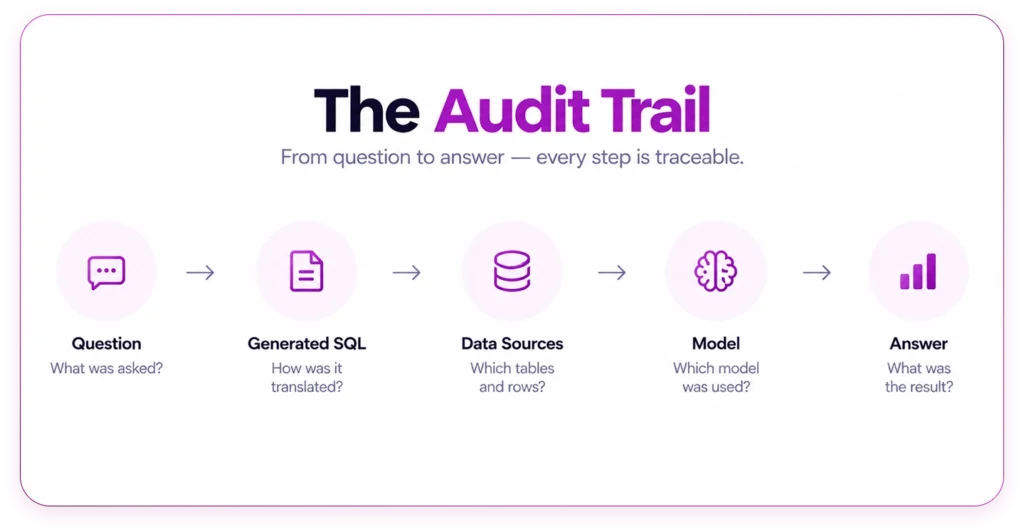
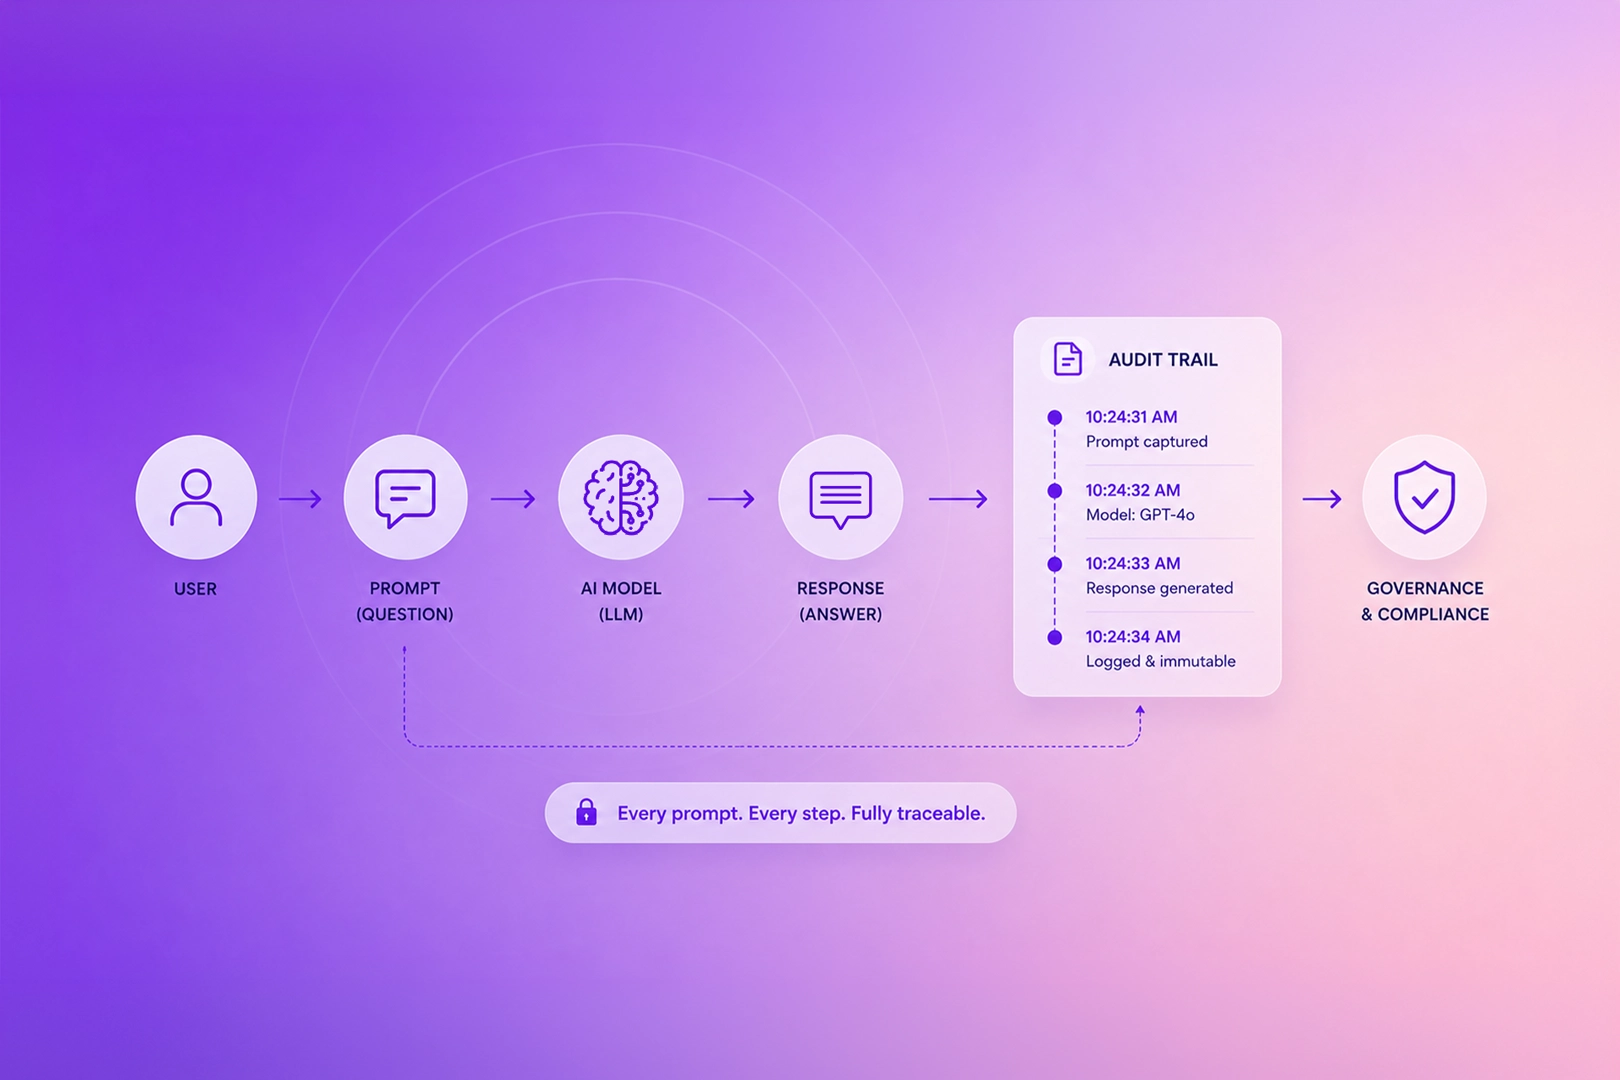
    Every question asked of an agent should produce two artefacts: the answer, and the record of how the answer was produced. The audit pillar means logging the full chain on every interaction: who asked, what they asked, which SQL the agent generated, which tables and rows it touched, which model produced the reasoning, and what came back. This is the prompt-level audit trail, and it is the difference between an answer you can act on and an answer you can defend.

    Without it, every agent response is an orphan. When a number in a board deck is challenged three months later, there is no way to reconstruct where it came from. Internal audit cannot test the system. Regulators in banking, insurance, and healthcare cannot accept its outputs as evidence. The absence of an audit trail does not make an agent less useful day to day. It makes the agent indefensible on exactly the day it matters most.

    Pillar two: the semantic layer

    An agent is only as accurate as its understanding of what the business means by its own words. The semantic pillar supplies that understanding: certified definitions of metrics, dimensions, and business terms that the agent consults before it writes a line of SQL. When someone asks about net revenue, the agent does not guess which of the fourteen revenue-adjacent columns in the warehouse to use. It uses the one the business certified.

    QuaerisAI’s Smart Semantic Layer adds a property that distinguishes it from manually authored alternatives: it learns. When an analyst corrects a definition or refines a query, the correction feeds back into the layer, so the next person asking a similar question benefits from it. Without a semantic layer of some kind, an agent hallucinates business logic, and it does so fluently, which is worse than failing loudly. Confidently wrong answers are the fastest way to destroy trust in an analytics deployment.

    Pillar three: the agentic layer

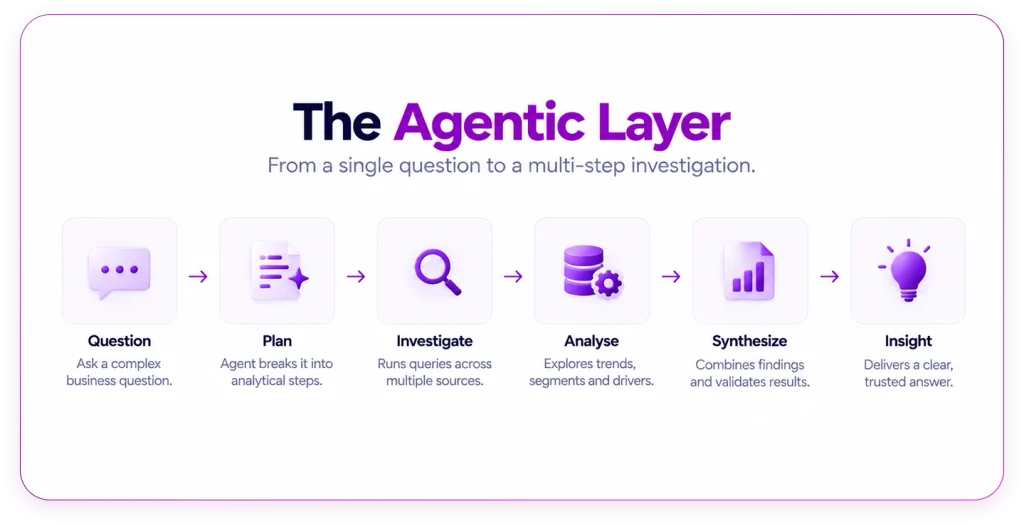
    The agentic pillar is what makes the platform more than search. Real analytical questions are rarely answered by one query. Why did margin dip in the northeast last quarter is a plan: pull the margin trend, decompose it by product line, check input costs, compare against the same period last year, and assemble a finding. The agentic layer is the capability to decompose a question into steps, execute them across structured and unstructured sources, and synthesise a result, autonomously.

    Without it, the platform is a text-to-SQL translator: useful for single-shot lookups, incapable of investigation. The user gets a number when they needed an explanation. The distinction matters commercially because the investigation work is where the senior-staff hours actually go. Based on QuaerisAI customer deployments and published materials, agentic deployment in audit engagements has reduced standard engagement time from 170 hours to 70 hours, a 59 percent reduction, precisely because the multi-step work is where the time was.

    Pillar four: BYOM

    Bring your own model means the platform runs on the language model the enterprise chooses, whether from Anthropic, OpenAI, Google, or Meta, rather than binding the customer to a single vendor’s model. This pillar looks like a procurement detail until the first time it is tested. A compliance team mandates a specific model for data-residency reasons. A model vendor changes pricing. A new model release outperforms the incumbent on SQL generation. In a BYOM architecture, each of these is a configuration decision. In a locked architecture, each is a re-platforming project.

    BYOM also changes the negotiating position. An enterprise that can switch models holds pricing power an enterprise that cannot switch has surrendered. And for regulated buyers, model choice is increasingly a compliance requirement in its own right, because model provenance is becoming part of what auditors and regulators expect organisations to document.

    Why the pillars only work together

    The four pillars are not a feature list. They are load-bearing in combination. The audit trail is only meaningful if the semantic layer makes answers deterministic enough to be worth auditing. The semantic layer only pays for itself when an agentic layer is asking it thousands of questions a day. The agentic layer is only deployable in the enterprise because the audit trail makes its autonomy accountable. And BYOM keeps the whole structure durable as the model market shifts underneath it.

    This is why assembling the equivalent from point solutions rarely works. A logging tool, a metrics store, an agent framework, and a model gateway from four vendors produce four integration seams, and governance fails at seams. Governed Agentic Analytics is one architecture, and the four pillars are its definition.

    Frequently asked questions

    Which pillar should an evaluation test first?

    The audit trail, because it is the hardest to retrofit and the easiest to verify in a demo. Ask the vendor to show the complete record for a single query: the prompt, the generated SQL, the tables touched, the model used, and the result. If that record does not exist or requires engineering effort to produce, the other three pillars are standing on sand.

    Is a semantic layer still necessary if the model is very capable?

    Yes. Model capability improves general reasoning, but no model can know that your finance team excludes intercompany transfers from net revenue, or that fiscal Q1 starts in February. Those are facts about your business, not facts about the world, and they have to be supplied by a governed definition layer. Stronger models make the semantic layer more valuable, not less, because they execute certified definitions more reliably.

    Does BYOM mean the customer manages model infrastructure?

    No. BYOM in the QuaerisAI architecture means the customer selects which model powers the platform, from providers including Anthropic, OpenAI, Google, and Meta, and can change that selection. The platform handles the integration. The customer holds the choice.

  • The Prompt-Level Audit Trail: a new requirement for enterprise AI

    The Prompt-Level Audit Trail: a new requirement for enterprise AI

    Picture an internal auditor in 2027 reviewing how a critical business decision was made. The decision rested on a number, and the number came from an AI agent. The auditor asks the obvious questions. Who asked for this analysis? What exactly did they ask? What query did the system run? Which data did it read? Which model reasoned over it? For most AI analytics deployments today, the honest answer to all five questions is the same: we don’t know. The answer appeared in a chat window, the chat was cleared, and the chain of evidence never existed.

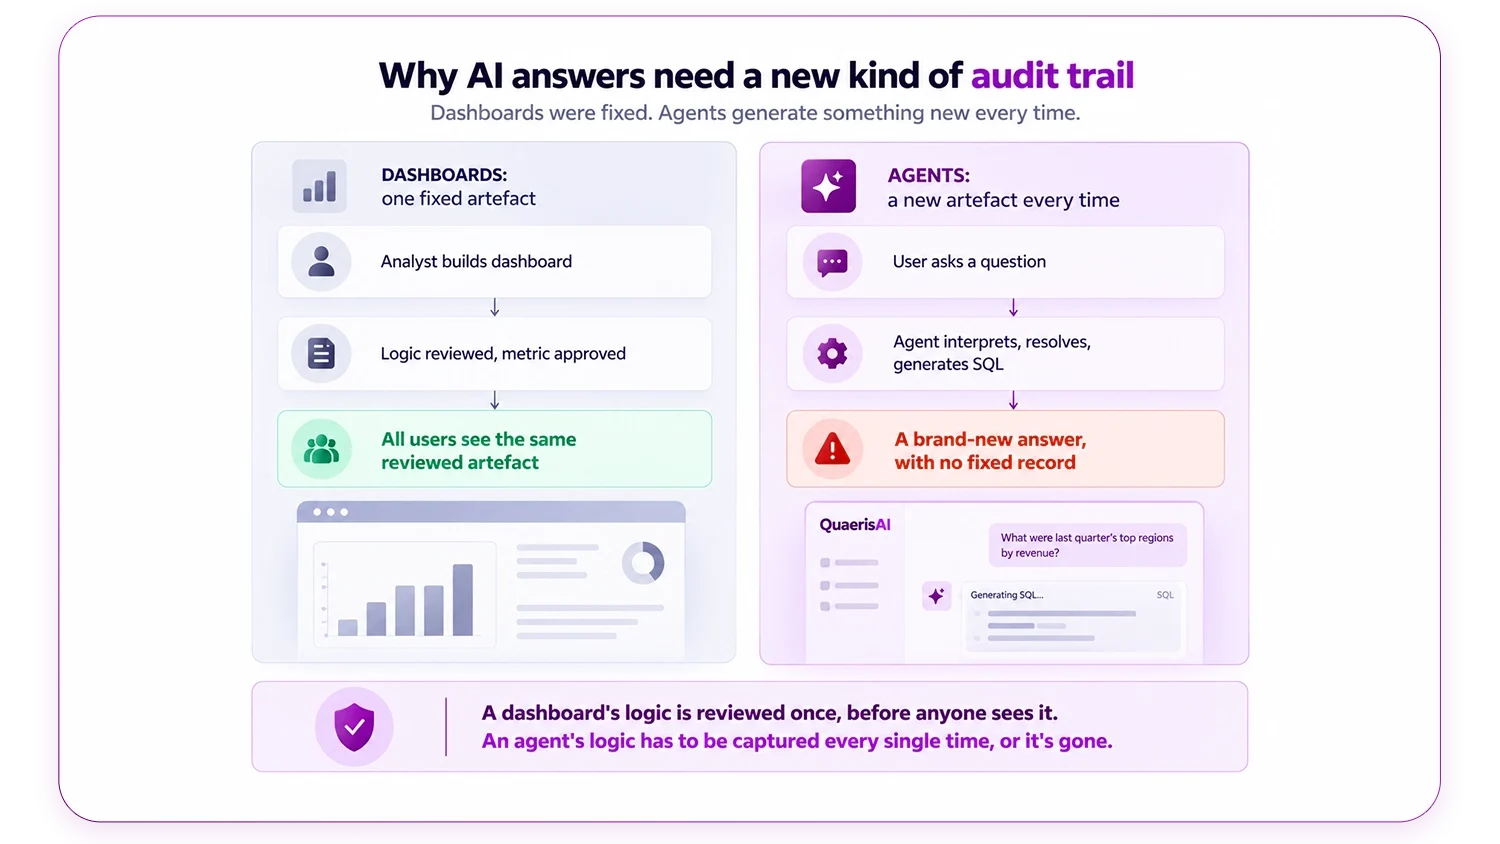
    Dashboards never had this problem, because dashboards never generated anything. A dashboard is a reviewed artefact: someone built it, someone approved it, and its logic sits in version control. Agentic analytics breaks that model. Every answer an agent produces is a new, never-before-reviewed piece of analysis, generated at the moment of asking. If enterprises are going to run on answers generated this way, and they are, then the review has to move from before publication to after the fact, and after-the-fact review requires a record. That record is the prompt-level audit trail.

    What a prompt-level audit trail contains

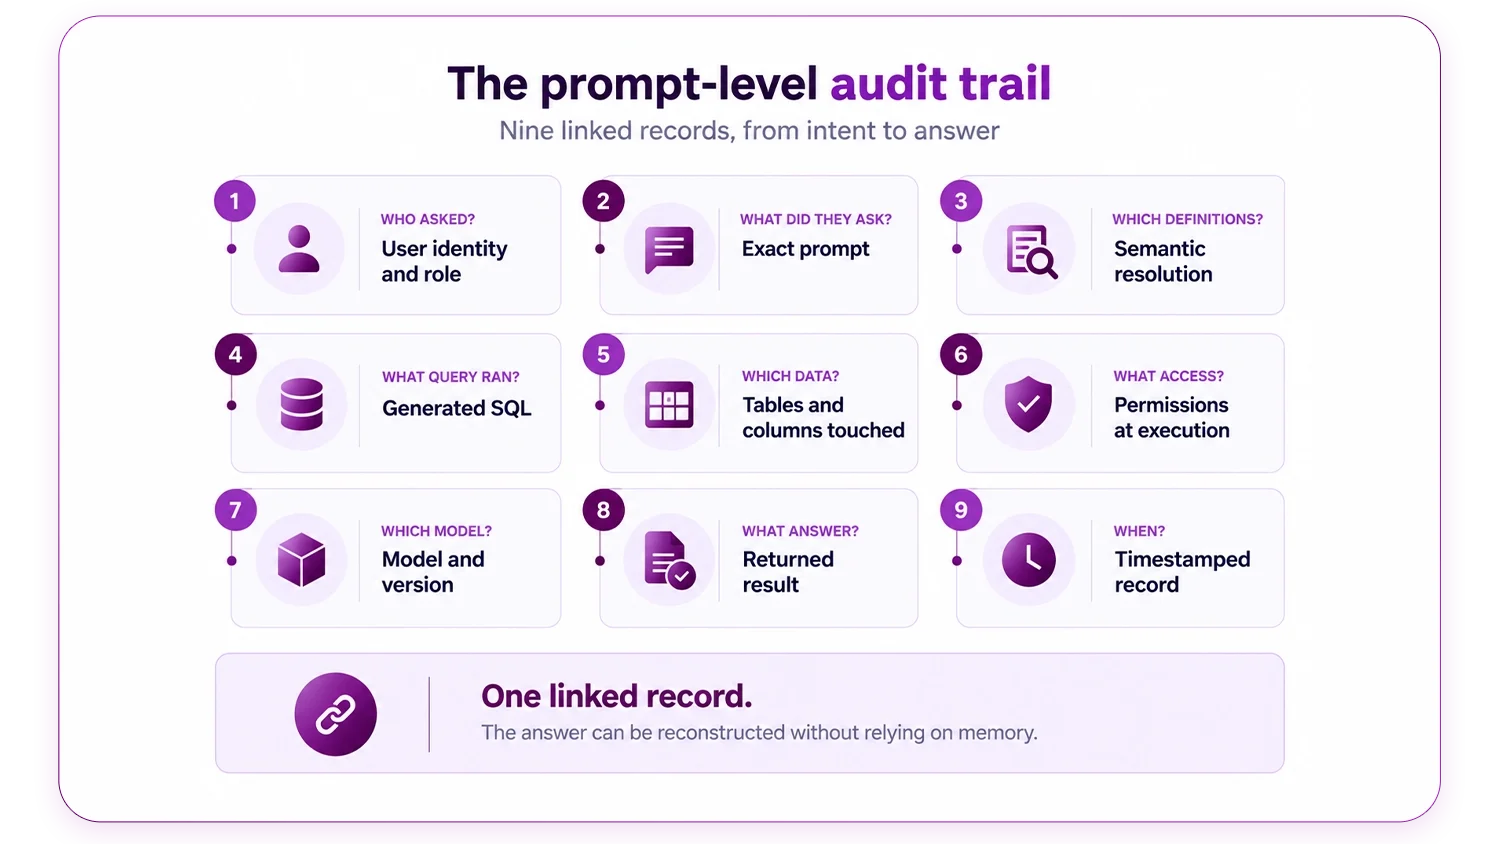
    The name is precise. The trail begins at the prompt, not at the query, because the prompt is where intent lives and where accountability starts. A complete trail captures the identity and role of the person asking, the exact wording of their question, the semantic definitions the platform resolved that question against, the SQL the agent generated, the tables and columns that SQL touched, the access permissions in force at the moment of execution, the model that produced the reasoning and its version, the result returned, and the timestamp of every step.

    Captured together, these fields make any answer reconstructible. Six months after the fact, a reviewer can replay the entire chain: this person, with these permissions, asked this question, which resolved to these certified definitions, which produced this SQL, which read these tables, which returned this number. Nothing in the chain depends on anyone’s memory. That is the standard evidence has always been held to everywhere else in the enterprise, and there is no reason AI-generated analysis should be exempt.

    Why the requirement is arriving now

    Three forces are converging on the same demand. Regulators are the first. Frameworks emerging around AI in the EU, in US state legislation, and in sector rules for insurance and healthcare differ in scope and timing, but they share a common thread: organisations deploying AI in consequential decisions must be able to document and explain what the system did. Documentation requires logs. Logs of AI-generated analysis are, by definition, prompt-level audit trails. Specific obligations and enforcement dates vary by jurisdiction and continue to shift, so legal teams should confirm current requirements, but the direction of travel is uniform.

    Auditors are the second force. External audit firms are extending their testing to cover AI-assisted processes at their clients, and an AI system whose outputs cannot be traced is an AI system whose outputs cannot be relied upon in an audit. The third force is internal, and it may be the strongest: executives are increasingly unwilling to carry numbers into board meetings that no one can stand behind. The first time a CFO is asked “where did this figure come from” and the answer is “an AI produced it, and we cannot show how,” the organisation acquires a prompt-level audit trail requirement regardless of what any regulator says.

    What the trail makes possible

    Compliance is the mandate, but it is not the only return. A complete trail is also the mechanism for disproving hallucination claims: when a stakeholder challenges an answer, the SQL and source tables are right there, and the dispute resolves on evidence in minutes rather than on reputation over weeks. It is a quality feedback loop: reviewing trails reveals where users phrase questions the semantic layer handles poorly, which is exactly the signal needed to improve it. And it is an adoption asset. People trust tools whose work they can check. Based on QuaerisAI customer deployments and published materials, governed deployments where every answer is traceable achieve BI adoption rates of 30 to 60 percent, and trust in the answer is a large part of why.

    Retrofit is not a strategy

    The tempting position is to deploy agents now and add logging when a regulator or auditor asks. This fails for an architectural reason. A trail that captures the prompt, the semantic resolution, the permission check, and the generated SQL as one linked record can only be produced by a platform in which those steps are one pipeline. Bolting a logger onto a system that was not built this way yields fragments: a chat log here, a database query log there, with no reliable join between them. The auditor’s question is not “do you have logs.” It is “can you show me the chain.” Chains are built in, or they do not exist.

    The prompt-level audit trail is on its way to becoming what SOC 2 became for SaaS: a requirement no serious buyer waives. The enterprises adopting it now are not doing extra work. They are doing the work once, before it becomes urgent.

    Frequently asked questions

    How is a prompt-level audit trail different from standard database query logging?

    Database logs capture what SQL ran and when. They do not capture who asked the business question, what they actually asked, how the question was interpreted against certified definitions, or which model generated the query. A prompt-level audit trail links the entire chain from human intent to returned result in one record. Query logs are one field within it, not a substitute for it.

    How long should prompt-level audit records be retained?

    Retention should follow the same schedule the organisation applies to the underlying business records the analysis supports, which varies by industry and jurisdiction. Financial analysis feeding reported results typically inherits multi-year retention obligations. The safe default is to align AI audit records with the retention class of the decisions they informed, and to confirm the specifics with compliance counsel.

    Does capturing prompts create a privacy problem?

    It creates a privacy design requirement, which is manageable. Prompts are user-generated content and should be handled under the same access controls as the data they touch: audit records themselves should be role-restricted, and access to them should be logged. A governed platform applies the same permission model to reading the trail as to querying the data.